Jun 28 - Jul 1, 2024Online and in person
Deception Detection Hackathon: Preventing AI deception
re you fascinated by the incredible advancements in AI? As AI becomes smarter and more powerful, it's essential that we make sure it always tells the truth and doesn't trick people. Imagine if an AI could manipulate narratives or try to scheme—that could lead to serious problems!
Entries
- 1st place by peer reviewView project: Sandbag Detection through Model Degradation
Sandbag Detection through Model Degradation
Team Truth Serum
We propose a novel technique to detect sandbagging in LLMs by adding varying amount of noise to model weights and monitoring performance.
- View project: DETECTING AND CONTROLLING DECEPTIVE REPRESENTATION IN LLMS WITH REPRESENTATIONAL ENGINEERING
DETECTING AND CONTROLLING DECEPTIVE REPRESENTATION IN LLMS WITH REPRESENTATIONAL ENGINEERING
Team DeceptionRepE
Representation Engineering to detect and control deception, with a focus on deceptive sandbagging
- View project: Can Language Models Sandbag Manipulation?
Can Language Models Sandbag Manipulation?
Team Can Language Models Sandbag Manipulation?
We are expanding on Felix Hofstätter's paper on LLM's ability to sandbag(intentionally perform worse), by exploring if they can sandbag manipulation tasks by using the "Make Me Pay" eval, where agents try to manipulate eachother into giving money to eachother
- View project: Deceptive behavior does not seem to be reducible to a single vector
Deceptive behavior does not seem to be reducible to a single vector
Team Whitebox Research
Given the success of previous work in showing that complex behaviors in LLMs can be mediated by single directions or vectors, such as refusing to answer potentially harmful prompts, we investigated if we can create a similar vector but for enforcing to answer incorrectly. To create this vector we used questions from …
- View project: Detecting Lies of (C)omission
Detecting Lies of (C)omission
Team
We introduce the concept of deceptive omission to denote deceptive non-lying behavior. We also modify a dataset and generate a second dataset to help researchers identify deception that doesn't necessarily involve lying.
- View project: Werewolf Benchmark
Werewolf Benchmark
Team WolfBench
In this work we put forward a benchmark to quantitatively measure the level of strategic deception in LLMs using the Werewolf game. We run 6 different setups for a cumulative sum of 500 games with GPT and Claude agents. We demonstrate that state-of-the-art models perform no better than the random baseline. Our …
- View project: Detecting Deception with AI Tics 😉
Detecting Deception with AI Tics 😉
Team Polygraph
We present a novel approach: intentionally inducing subtle "tics" in AI responses as a marker for deceptive behavior. By adding a system prompt, we embed innocuous yet detectable patterns that manifest when the AI knowingly engages in deception.
- View project: The House Always Wins: A Framework for Evaluating Strategic Deception in LLMs
The House Always Wins: A Framework for Evaluating Strategic Deception in LLMs
Team Multivac
We propose a framework for evaluating strategic deception in large language models (LLMs). In this framework, an LLM acts as a game master in two scenarios: one with random game mechanics and another where it can choose between random or deliberate actions. As an example, we use blackjack because the action space nor …
- View project: Eliciting maximally distressing questions for deceptive LLMs
Eliciting maximally distressing questions for deceptive LLMs
This paper extends lie-eliciting techniques by using reinforcement-learning on GPT-2 to train it to distinguish between an agent that is truthful from one that is deceptive, and have questions that generate maximally different embeddings for an honest agent as opposed to a deceptive one.
- View project: Evaluating Steering Methods for Deceptive Behavior Control in LLMs
Evaluating Steering Methods for Deceptive Behavior Control in LLMs
Team Deception Detecion Ninjas
We use SOTA steering methods, including CAA, LAT, and SAEs to find and control deceptive behaviors in LLMs. We also release a new deception dataset, and demonstrate that the dataset and the prompt formatting used are significant when evaluating the efficacy of steering methods.
- View project: An Exploration of Current Theory of Mind Evals
An Exploration of Current Theory of Mind Evals
Team AgentToM
We evaluated the performance of a prominent large language model from Anthropic, on the Theory of Mind evaluation developed by the AI Safety Institute (AISI). Our investigation revealed issues with the dataset used by AISI for this evaluation.
- View project: Detecting Deception in GPT-3.5-turbo: A Metadata-Based Approach
Detecting Deception in GPT-3.5-turbo: A Metadata-Based Approach
Team onlyW
This project investigates deception detection in GPT-3.5-turbo using response metadata. Researchers analyzed 300 prompts, generating 1200 responses (600 baseline, 600 potentially deceptive). They examined metrics like response times, token counts, and sentiment scores, developing a custom algorithm for prompt …
- View project: Sandbagging LLMs using Activation Steering
Sandbagging LLMs using Activation Steering
Team AI Safety Initiative Groningen
As advanced AI systems continue to evolve, concerns about their potential risks and misuses have prompted governments and researchers to develop safety benchmarks to evaluate their trustworthiness. However, a new threat model has emerged, known as "sandbagging," where AI systems strategically underperform during …
- View project: Towards a Benchmark for Self-Correction on Model-Attributed Misinformation
Towards a Benchmark for Self-Correction on Model-Attributed Misinformation
Team A&K
Deception may occur incidentally when models fail to correct false statements. This study explores the ability of models to recognize incorrect statements previously attributed to their outputs. A conversation is constructed where the user asks a generally false statement, the model responds that it is factual and the …
- View project: Boosting Language Model Honesty with Truthful Suffixes
Boosting Language Model Honesty with Truthful Suffixes
Team Honest Algorithms, Eh
We investigate the construction of truthful suffixes, which cause models to provide more truthful responses to user queries. Prior research has focused on the use of adversarial suffixes for jailbreaking; we extend this to causing truthful behaviour.
- View project: Detection of potentially deceptive attitudes using expression style analysis
Detection of potentially deceptive attitudes using expression style analysis
Team ClarityNaut
My work on this hackathon consists of two parts: 1) As a sanity check, verifying the deception execution capability of GPT4. The conclusion is “definitely yes”. I provide a few arguments about when that is a useful functionality. 2) Experimenting with recognising potential deception by using an LLM-based text analysis …
- View project: From Sycophancy (not) to Sandbagging
From Sycophancy (not) to Sandbagging
Team The Sandbaggers
We investigate zero-shot generalization of sycophancy to sandbagging. We develop an evaluation suite and test harness for Huggingface models, consisting of a simple sycophancy evaluation dataset and a more advanced sandbagging evaluation dataset. For Llama3-8b-Instruct, we do not find evidence that reinforcing …
- View project: Gradient-Based Deceptive Trigger Discovery
Gradient-Based Deceptive Trigger Discovery
Team The Deceptive Triggers
To detect deceptive behavior in autoregressive transformers we ask the question: what variation of the input would lead to deceptive behavior? To this end, we propose to leverage the research direction of prompt optimization and use a gradient-based search method GCG to find which specific trigger words would cause …
- View project: Modelling the oversight of automated interpretability against deceptive agents on sparse autoencoders
Modelling the oversight of automated interpretability against deceptive agents on sparse autoencoders
Team Simomatt
Sparse autoencoders (SAE) have been one of the most promising approaches to neural network interpretability. They can be used to recover highly interpretable features which are otherwise obscured in superposition. However, the large num- ber of generated features makes it necessary to use models for natural language …
- View project: Evaluating and inducing steganography in LLMs
Evaluating and inducing steganography in LLMs
This report demonstrates that large language models are capable of hiding simple 8 bit information in their output using associations from more powerful overseers (other LLMs or humans). Without direct steganography fine tuning, LLAMA 3 8B can guess a 8 bit hidden message in a plain text in most cases (69%), however a …
- View project: Developing a deception dataset
Developing a deception dataset
Team Lovkush
Aim was to develop dataset of deception examples, but instead was a (small) investigation into how LLMs respond to the initial dataset from Nix.
Overview
Are you fascinated by the incredible advancements in AI? As AI becomes smarter and more powerful, it's essential that we make sure it always tells the truth and doesn't trick people. Imagine if an AI could manipulate narratives or try to scheme—that could lead to serious problems!
That's where you come in. We're inviting you to join the Deception Detection Hackathon, an exciting event where you'll team up with researchers, programmers, and AI safety experts to create amazing pilot experiments to spot when an AI is being deceptive (and potentially reducing deceptive tendencies!). Over one thrilling weekend, you'll put your skills to the test and develop cutting-edge techniques to keep AI honest and trustworthy.
Why deception detection matters
Deception in AI, a concept severely under-explored, occurs when an AI system is capable of deceiving a user, either designed for it by a malicious actor or due to misaligned goals. Such systems may appear to be aligned with users and humans values during training and evaluation but pursue malign objectives when deployed, potentially causing harm or undermining trust in AI.
Examples of such work can be found in:
- Situational Awareness Benchmark: An evaluation of how well models can identify what state they are in (hackathon project, talk)
- LLM Identification Benchmark: Can an LLM identify whether a human or an LLM wrote a text? Might be important for self-coordination across chat instances (similar hackathon project)
- Strategic Deception Report: An example of strategic deception presented by Apollo Research at the AI Safety Summit 2023 (explainer)
To mitigate these risks, we must develop robust deception detection methods that can identify instances of strategic deception, make headway on understanding AI capabilities for deception, and prevent AI systems from misleading humans. By participating in this hackathon, you'll contribute to the critical task of ensuring that AI remains transparent, accountable, and aligned with human values.
Contribute to AGI deception research
During the hackathon, you'll have the opportunity to:
- Learn from experts in AI safety, deceptive alignment, and strategic deception
- Collaborate with a diverse group of participants to ideate and develop deception detection techniques
- Create benchmarks and evaluation methods to assess the effectiveness of deception detection approaches
- Compete for prizes and recognition for the most innovative and impactful solutions
- Network with like-minded individuals passionate about ensuring the safety and trustworthiness of AI
Whether you're an AI researcher, developer, or enthusiast, this hackathon provides a unique platform to apply your skills and knowledge to address one of the most pressing challenges in AI safety.
Join us in late June for a weekend of collaboration, innovation, and problem-solving as we work together to prevent AI from deceiving humans. Stay tuned for more details on the exact dates, format, and registration process.
Don't miss this opportunity to contribute to the development of trustworthy AI systems and help shape a future where AI and humans can work together safely and transparently. Let's hack for a deception-free AI future!
Prizes, evaluation, and submission
You will join in teams to submit a PDF about your research according to the submission template shared in the submission tab! Depending on the judge's reviews, you'll have the chance to win from the $2,000 prize pool! Find the review criteria on the submission tab.
- 🥇 $1,000 for the top team
- 🥈 $600 for the second prize
- 🥉 $300 for the third prize
- 🏅 $100 for the fourth prize
What is a research hackathon?
The AGI Deception Detection Hackathon is a weekend-long event where you participate in teams (1-5) to create interesting, fun, and impactful research. You submit a PDF report that summarizes and discusses your findings in the context of AI safety. These reports will be judged by our panel and you can win up to $1,000!
It runs from 28th June to 1st July and we're excited to welcome you for a weekend of engaging research. You will hear fascinating talks about real-world projects tackling these types of questions, get the opportunity to discuss your ideas with experienced mentors, and you will get reviews from top-tier researchers in the field of AI safety to further your exploration.
Everyone can participate and we encourage you to join especially if you’re considering AI safety from another career. We give you code templates and ideas to kickstart your projects and you’ll be surprised what you can accomplish in just a weekend – especially with your new-found community!
Read more about what you can expect, the schedule, and what previous participants have said about being part of the hackathon below.
Why should I join?
There’s loads of reasons to join! Here are just a few:
- See how fun and interesting AI safety can be
- Get to know new people who are into the overlap of empirical ML safety and AI governance
- Win up to $1,000, helping you towards your first H100 GPU
- Get practical experience with LLM evaluations and AI safety research
- Show the AI safety labs what you are able to do to increase your chances at some amazing jobs
- Get a certificate at the end!
- Get proof that your work is awesome so you can get that grant to pursue the AI safety research that you always wanted to pursue
- The best teams are offered to participate in the Apart Lab program, which supports teams in their journey towards publishing groundbreaking AI safety and security research
- And many many more… Come along!
Do I need experience in AI safety to join?
Please join! This can be your first foray into AI and ML safety and maybe you’ll realize that there are exciting low-hanging fruit that your specific skillset is adapted to. Even if you normally don’t find it particularly interesting, this time you might see it in a new light!
There’s a lot of pressure from AI safety to perform at a top level and this seems to drive some people out of the field. We’d love it if you consider joining with a mindset of fun exploration and get a positive experience out of the weekend.
What are previous experiences from the research hackathon?
Yoann Poupart, BlockLoads CTO: "This Hackathon was a perfect blend of learning, testing, and collaboration on cutting-edge AI Safety research. I really feel that I gained practical knowledge that cannot be learned only by reading articles.”
Lucie Philippon, France Pacific Territories Economic Committee: "It was great meeting such cool people to work with over the weekend! I did not know any of the other people in my group at first, and now I'm looking forward to working with them again on research projects! The organizers were also super helpful and contributed a lot to the success of our project.”
Akash Kundu, now an Apart Lab fellow: "It was an amazing experience working with people I didn't even know before the hackathon. All three of my teammates were extremely spread out, while I am from India, my teammates were from New York and Taiwan. It was amazing how we pulled this off in 48 hours in spite of the time difference. Moreover, the mentors were extremely encouraging and supportive which helped us gain clarity whenever we got stuck and helped us create an interesting project in the end.”
Nora Petrova, ML Engineer at Prolific: “The hackathon really helped me to be embedded in a community where everyone was working on the same topic. There was a lot of curiosity and interest in the community. Getting feedback from others was interesting as well and I could see how other researchers perceived my project. It was also really interesting to see all the other projects and it was positive to see other's work on it.”
Chris Mathwin, MATS Scholar: "The Interpretability Hackathon exceeded my expectations, it was incredibly well organized with an intelligently curated list of very helpful resources. I had a lot of fun participating and genuinely feel I was able to learn significantly more than I would have, had I spent my time elsewhere. I highly recommend these events to anyone who is interested in this sort of work!”
What if my research seems too risky to share?
Besides emphasizing the introduction of concrete mitigation ideas for the risks presented, we are aware that projects emerging from this hackathon might pose a risk if disseminated irresponsibly.
For all of Apart's research events and dissemination, we follow our Responsible Disclosure Policy.
Resources
We have collected a few exciting resources about deception, both to get you started with research in this area but also to dive even deeper. Required reading:
- Check out the Deception Detection Hackbook to train your own Sleeper Agent and get inspired
- Examples of deception in AI systems written by Park et al. 2023 (pages 2 to 10)
Optional research articles on concepts related to deception detection:
- Research attempting to detect deception in AI systems
- The Situational Awareness Benchmark (Laine et al., 2024) takes steps towards understanding when language models know which situation they're in, a property important to be able to execute strategic deception, such as sandbagging
- The GDM frontier evals paper (Phuong et al., 2024) includes a section on autonomy and includes good tasks to test applied situational awareness
- Burns et al. (2024) use a form of PCA on neural network activation to identify whether a language model is lying or not
- Zou et al. (2023) use neural population modeling to develop "representation engineering", a method to understand a neural network's representation of high-level concepts, such as "honesty", "morality", and "emotions"
- Azaria & Mitchell (2023) classify whether a statement is true or false based on activations in a language model, leading to an understanding of when a model might be lying
- Pacchiardi et al. (2023) use a black-box method (where we don't have access to model internals) to ask unrelated follow-up questions and use the model's answers to understand whether it's lying or not
- Kuhn et al. (2023) measure the uncertainty of a language model's responses
- Anthropic (2024) uses "linear probes" (simple statistics on neural network activation) to catch sleeper agents (see the definition in the paper further down)
- Research introducing methods for reducing deception and trustworthy design
- Quirke et al. (2024) introduce an example mitigation where we "install" verified circuits into neural networks to trust a specific sub-process in a network
- Li et al. (2023) use activation steering to increase honesty and truthfulness in a Llama model after deployment (inference-time)
- In Hubinger et al. (2024), Anthropic shows that so-called "Sleeper agents" (LLMs trained to be deceptive) are very difficult to inspect and remove harmfulness from (w/ involvement from Apart)
- Related research work exploring the frontier of capabilities that are potentially required for deception or is useful for your work during the weekend
- Kinniment et al. (2024) describes methods to use challenges to evaluate models for the ability for autonomy and autonomous research and development - you might find inspiration for developing agent architectures to test for deception in this (and possibly find this METR research useful as well)
- AISI published their fourth progress report with evaluation metrics on various models for 1) ability to program and do cyber operations, 2) show knowledge of chemistry and biology, 3) ability to work autonomously, and 4) security against malicious attacks.
- AISI also published inspect, a framework for large language model (LLM) evaluations, that might be useful for your work
- Woodside et al. (2023) published an updated list of examples where AI is used to improve AI systems, showing an example of a collaborative literature review project
Optional reading about the potential for deception in superintelligent systems:
- In this work by Hubinger et al. (2021), they explore the theoretical tendency of neural networks to have internal goals that might not be aligned with what the creator wants
- Carlsmith (2023) explores the high possibility that machine learning actually incentivizes deception / scheming
- Weij et al. (2024) introduces the concept of "sandbagging" in AI systems, the potential for models to strategically underperform during evaluation to fool an auditor or engineer
- Scheurer (2024) is an Apollo Research project presented at the AI Safety Summit in UK, showing a preliminary demonstration of an LLM strategically deceiving humans
Additionally, we have previously hosted hackathons where related work was submitted. You can find a few examples here to find inspiration for where you might be able to take your project during the weekend. You can find examples on the Sprints page.
Schedule
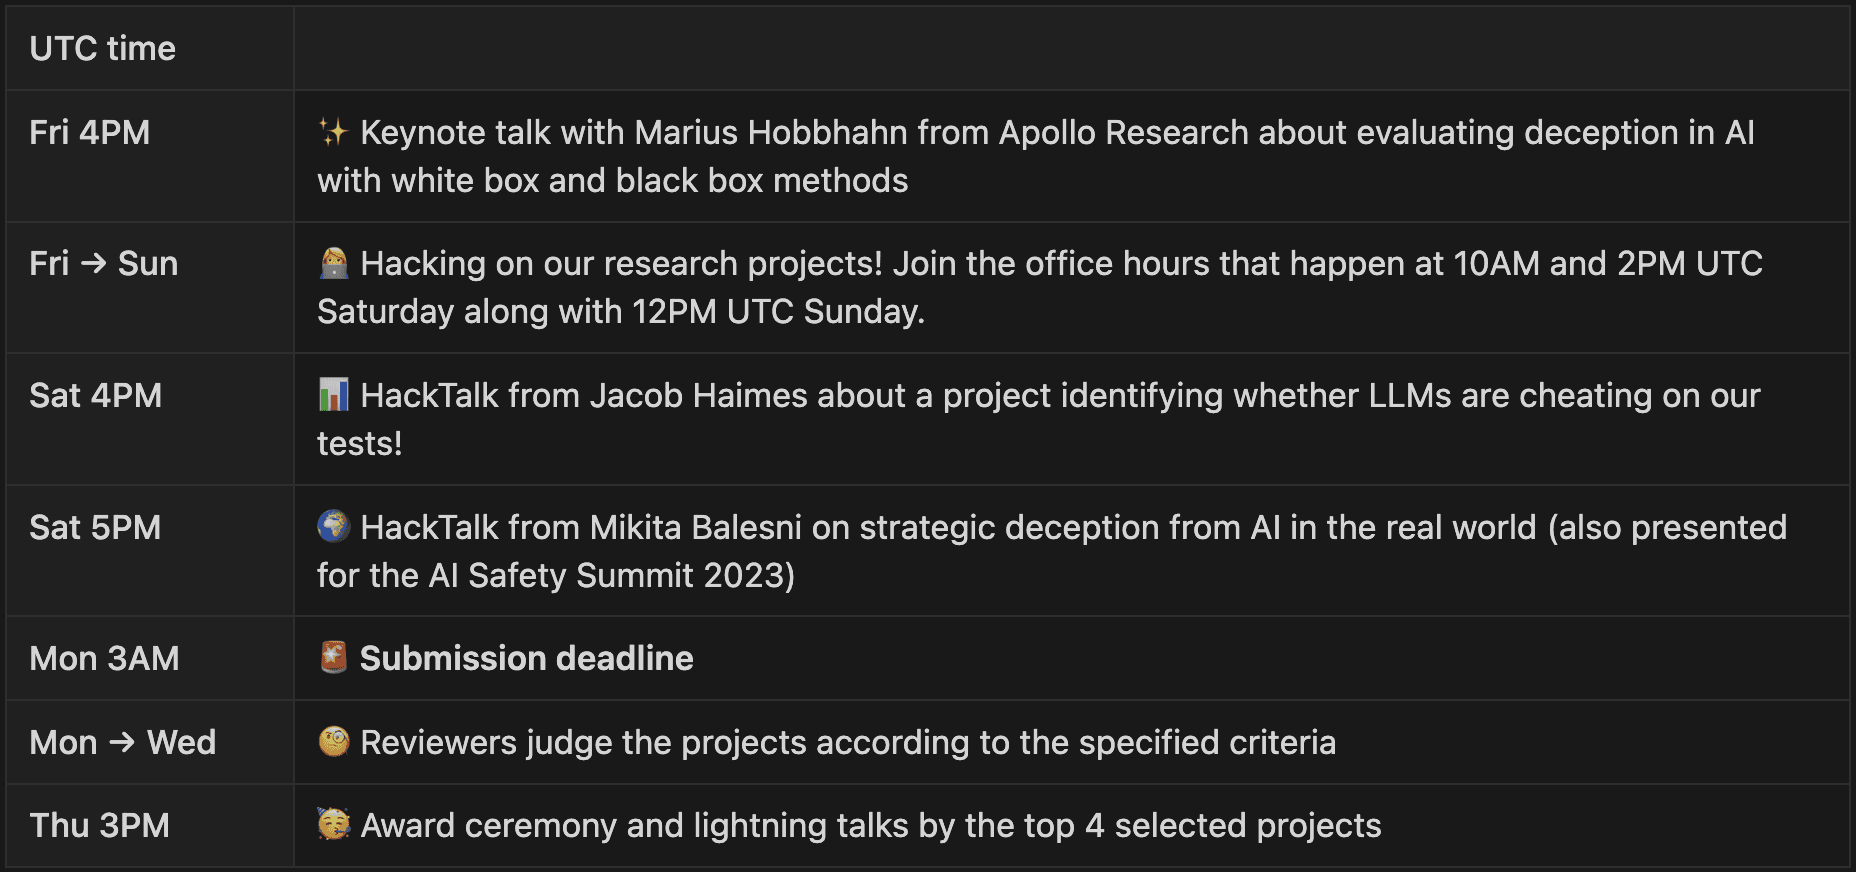
The schedule runs from 4 PM UTC Friday to 3 AM Monday. We start with an introductory talk and end the event during the following week with an awards ceremony. Join the public ICal here.
You will also find Explorer events such as collaborative brainstorming and team match-making before the hackathon begins on Discord and in the calendar.
Speakers
Esben Kran
Organizer and Keynote Speaker
Esben is the founder of Apart Research, which he launched at age 22 after leaving grad school. Apart accelerates AI safety research worldwide, producing 20+ papers, award-winning benchmarks like DarkBench, and engaging 4,000+ hackers in research sprints.
Recently co-launched Seldon to fund critical infrastructure for humanity's future, with first investments in Andon Labs, Lucid Computing, Workshop Labs, and Asymmetric Security.
Jacob Haimes
Speaker & Mentor
Author of the unpublished retro-holdout paper about evaluation datasets that have leaked into the training set and a fellow at the Apart Lab. Hosts a podcast on AI safety.
Mikita Balesni
Speaker
Mikita is a research scientist at Apollo Research and works on evaluation of dangerous language model capabilities. He helped Ukraine's cyber front against the Russian invasion
Judges and mentors
Organizers
Local sites
AI Safety Initiative Groningen (aisig.org) - Deception Detection Hackathon
We will be hosting the hackathon at Hereplein 4, 9711GA, Groningen. Join us!
Event page: AI Safety Initiative Groningen (aisig.org) - Deception Detection Hackathon (opens in new tab)EA Tech London @ London Initiative for Safe AI: Deception Detection Hackathon
We'll be hosting a jam site at the LISA offices in Shoreditch (25 Holywell Row, London EC2A 4XE). Hang out and collaborate with others interested in, and working on, AI safety!
Event page: EA Tech London @ London Initiative for Safe AI: Deception Detection Hackathon (opens in new tab)WhiteBox Research - Manila Node of AI Deception Hackathon
WhiteBox is hosting the Manila node of the hackathon at Openspace Katipunan in 50 Esteban Abada St. on June 29-July 1. Join us!
Event page: WhiteBox Research - Manila Node of AI Deception Hackathon (opens in new tab)
Where a Sprint can lead
How our programs connectAnyone can join
Stand out
6 to 16 weeks on your own project, with a research project manager, compute and publication support.
Upcoming Sprints
All SprintsAI Collusion Research Sprint
A weekend research sprint on collusion between AI agents: when it emerges in markets and everyday workflows, how to detect and audit it, how it is carried, and what breaks it. Co-organized with Poseidon Research and AE Studio, online with in-person hubs at Collider in New York City and AI Safety Hong Kong. Top teams are invited to apply to the Apart Fellowship.
Read the brief: AI Collusion Research SprintAI x Epistemics Research Sprint
A weekend research sprint on AI for epistemics: evaluating whether models know how solid their claims are, building trust infrastructure that people and agents can consume, and shipping epistemic products that improve real decisions. Online, four tracks including an open track. Top teams are invited to apply to the Apart Fellowship.
Read the brief: AI x Epistemics Research SprintQuestions? sprints@apartresearch.com