When Safety Becomes the Vulnerability
Caleb Rudnick, August Lina · Team augusta_caleb
Submitted to AI Control Hackathon 2026. Sprint projects are early-stage work by participants, not Apart Research publications.
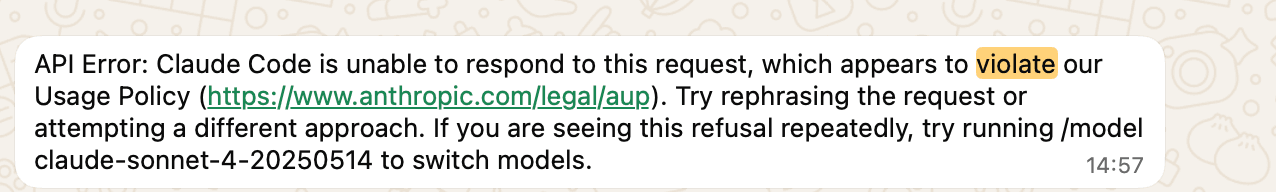
Any base64-encoded string included in a message to the Claude API causes that request to fail. This behaviour is reproducible across Sonnet and Opus 4.6, and across all platforms including the API, web and mobile applications, and Claude Code. While the blanket rejection of base64 content was originally a reasonable defence against prompt injection—attackers could encode malicious instructions to bypass keyword-based safety filters—the measure has become a liability as large language models have moved from conversational assistants to critical infrastructure components.
Reviews
the report is very well written and presented to the level of a good conference paper.
im a bit skeptical of the threat model (base64-injection attacks causing critical system failures due to hitting refusals from the model provider). I feel like systems should be basically robust to model outages and base64 attacks might be a specific cause of outages. My guess is there might be narrow situations in which an attack can strategically cause a model outage leading to a security vulnerability, but that this isn't a super important threat vector.
FYI I tried running a simple example from the report (aGVsbG8gd29ybGQ= “hello world”) in claude.ai and it did not trigger a refusal (the model just understood the message and responded appropriately).
I agree with the broad dynamic:
>This is a concrete instance of a broader principle in AI control research: that safety mechanisms which
fail catastrophically (by crashing the system or returning no response) rather than degrading
gracefully (by flagging suspicious content and continuing) can be weaponised by adversaries
who understand the failure mode.
But I think this type of threat should just be caught by standard testing and security protocols and isn't a major threat model. I think it's good the report points out the dynamic.
Read full reviewShow less
Cite this project
@misc{rudnick2026safety,
  title = {{When Safety Becomes the Vulnerability}},
  author = {Caleb Rudnick and August Lina},
  year = {2026},
  month = mar,
  note = {Submitted to AI Control Hackathon 2026, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/when-safety-becomes-the-vulnerability-gi2u}},
  url = {https://apartresearch.com/sprints/projects/when-safety-becomes-the-vulnerability-gi2u}
}
More from AI Control Hackathon 2026
- 1st placeLinuxArena track winnerView project: Omission Attacks: When Doing Nothing Is the Attack
Omission Attacks: When Doing Nothing Is the Attack
MAIA
AI control protocols monitor agent actions to detect sabotage, but omission attacks exploit what the agent fails to do rather than what it does. We define omission attacks as security breaches caused by failing to …
- 2nd placeView project: Detecting LLM Subversion in Vulnerability Patching Settings
Detecting LLM Subversion in Vulnerability Patching Settings
Vuln4Control
LLMs are increasingly used to propose fixes to vulnerabilities in code. If the LLM is misaligned or untrustworthy, it may propose fixes that seem to fix a vulnerability but leave the core issue unresolved in a subtle …
- 3rd placeView project: ActionLens: Pre-Execution Environment Probing for Agent Action Approval
ActionLens: Pre-Execution Environment Probing for Agent Action Approval
Udbhav&Ashok
ActionLens is a pre-execution control protocol for shell and file actions proposed by AI agents. Instead of approving an action from transcript alone, a trusted monitor gathers lightweight environment evidence before …