May 30 - Jun 1, 2025Online
Apart x Martian Mechanistic Router Interpretability Hackathon
Join the effort to make AI orchestration interpretable from the ground up—where judge models reveal their reasoning process and routing decisions become windows into AI decision-making!
Entries
- 1st place by peer reviewView project: Manipulating Self-Preference for Large Language Models
Manipulating Self-Preference for Large Language Models
Team Preference · Bellevue, WA
Large language models (LLMs) carry great value as evaluators of synthetic data for research and production settings. However, recent research shows that language models exhibit bias towards their own responses in blind model-to-model evaluation settings. Self-preference bias shows clear negative effects on effective …
- 2nd place by peer reviewView project: Approximating Human Preferences Using a Multi-Judge Learned System
Approximating Human Preferences Using a Multi-Judge Learned System
Team AutoBox · Buenos Aires
In this work, we introduced a learned approach to aggregating multi-judge scores: using a GAM and a simple MLP as an alternative to traditional, non-learned methods like averaging. Our models outperform the naive baseline in predicting simulated human preferences, demonstrating that learned aggregation can better …
- 3rd place by peer reviewView project: Judge using SAE Features
Judge using SAE Features
Team SAEwhat? · Mumbai, India
The key idea of this project was to explore model judgement using Sparse Autoencoder (SAE) features for mathematical reasoning tasks involving addition, multiplication, and subtraction operations. We compared this performance against basic Chain-of-Thought (CoT) based judgement using routing algorithms deployed by the …
- 4th place by peer reviewView project: Guardian-Loop: Mechanistically Interpretable Micro-Judges with Adversarial Self-Improvement
Guardian-Loop: Mechanistically Interpretable Micro-Judges with Adversarial Self-Improvement
Team Guardian Loop · London, UK
Guardian-Loop is a mechanistically interpretable judge system designed to enhance the Expert Orchestration Architecture through transparent and efficient safety evaluation. Targeting Track 1 (Judge Model Development), we train lightweight classifiers that pre-filter prompts for safety using a Llama 3.1 8B model, …
- View project: LLM Fingerprinting Through Semantic Variability
LLM Fingerprinting Through Semantic Variability
Team Hyper Holistic Revengs · Vienna / Copenhagen / Toronto
This project develops an LLM fingerprinting and analysis toolkit to increase transparency in AI routing systems, addressing Track 2: Intelligent Router Systems through two key investigations. We adapted semantic variability analysis to create unique behavioral fingerprints that can identify which specific models are …
- View project: Mechanistic Judging and LLM Routing: Evaluation, Task-Specific Vulnerabilities, and Exploitable Failure Mode
Mechanistic Judging and LLM Routing: Evaluation, Task-Specific Vulnerabilities, and Exploitable Failure Mode
Team Sahoo - the 1 Man Army · Cuttack,India
This research presents the development of a mechanistically interpretable LLM-based judging system with a novel routing algorithm. The implementation exclusively leverages the Qwen reasoning model architecture, establishing a foundation for transparent evaluation processes. Furthermore, we introduce innovative …
- View project: JASONTEST Guardian-Loop: Mechanistically Interpretable Micro-Judges with Adversarial Self-Improvement
JASONTEST Guardian-Loop: Mechanistically Interpretable Micro-Judges with Adversarial Self-Improvement
Team JASONTEST Guardian Loop · London, UK
Guardian-Loop is a mechanistically interpretable judge system designed to enhance the Expert Orchestration Architecture through transparent and efficient safety evaluation. Targeting Track 1 (Judge Model Development), we train lightweight classifiers that pre-filter prompts for safety using a Llama 3.1 8B model, …
- View project: Mechanistic Router for Interpretable Agent Orchestration
Mechanistic Router for Interpretable Agent Orchestration
Team Gamma Router · Toronto
This project presents a lightweight and interpretable routing system that selects among multiple reasoning strategies—Zero-Shot, Chain-of-Thought (CoT), Program-Aided Language (PAL), ReAct, and Few-Shot—based on features of the user query. It supports the vision of expert orchestration by treating large language model …
- View project: Reliability Judge: Enhancing LLM Reliability Through Multi-Model Judging
Reliability Judge: Enhancing LLM Reliability Through Multi-Model Judging
Team Reliability Judge · Buenos Aires, Argentina
We present a multi-model judging framework that extends the Think Twice before Trusting (T3) paradigm to enhance answer reliability across large language models (LLMs). Our approach is most suitable for high-stakes contexts (e.g., healthcare, legal, or safety-critical systems), where even minor accuracy gains can have …
- View project: Mechanistically Eliciting Misjudgements in Large Language Models
Mechanistically Eliciting Misjudgements in Large Language Models
Team Apart x AdvInput · Cambridge, London, Copenhagen
Large Language Models (LLMs) are being increasingly used in evaluator roles, called LLMs-as-a-Judge. This increases the importance of robustness. We investigate a technique for mechanistically eliciting latent behaviour called Deep Causal Transcoding (DCT) on Qwen2.5-3B to give incorrect evaluations. Our results show …
- View project: TOBIAS - better web pages through intelligent routing and judgement
TOBIAS - better web pages through intelligent routing and judgement
Team TOBIAS · Buenos Aires
We implemented routing and judging system designed to generate and evaluate improved versions of web page content for SEO, advertising and generative search goals. Our system selects the most promising content version using real-world performance indicators, providing a reproducible method for LLM benchmarking and …
- View project: Routing LLMs using Distilled Predictors and Confidence Thresholding
Routing LLMs using Distilled Predictors and Confidence Thresholding
Team Indie_Interp_Hacks · Chennai, India
This project explores confidence-based routing using sparsified transformer models as an intelligent alternative to monolithic AI systems. Focusing on Track 2: Intelligent Router Systems, we implemented a confidence-threshold router for a pruned DistilBERT model deployed via DeepSparse on the SST-2 sentiment …
- View project: A generalist Router for Inspect: Reasoning router demonstration
A generalist Router for Inspect: Reasoning router demonstration
Team The Interpreters · New Delhi, India
With hundreds of AI models available today, choosing the right model for each query is expensive and inefficient. We develop a system that learns compact "fingerprints" of different models and automatically routes questions to the most cost-effective option. Our approach achieves 96% of premium reasoning model …
- View project: Adversarial Vulnerabilities in AI Judge Models | Martian x Apart Research Study
Adversarial Vulnerabilities in AI Judge Models | Martian x Apart Research Study
Team Trajectory Labs · Toronto
This video presents systematic research examining security vulnerabilities in AI judge models - critical components used to detect problematic behavior in large language model systems. Our comprehensive evaluation reveals important findings for AI safety and orchestration systems. 🔬 RESEARCH OVERVIEW We conducted …
- View project: A Multidimensional Judge Model for Safe, Consistent and Ethical AI Orchestration
A Multidimensional Judge Model for Safe, Consistent and Ethical AI Orchestration
Team Sentinel! · Dubai, Helsinki and California
This project developed a multidimensional safety judge that transparently evaluates the outputs of large language models (LLMs) and AI routing systems across key safety dimensions: bias avoidance, factuality, manipulation resistance, and toxicity avoidance. By benchmarking both individual models and routed responses, …
- View project: People + Planet + Parity Governance Framework
People + Planet + Parity Governance Framework
Team Build People + Planet + Parity AI · Houston
This project introduces a governance framework to improve interpretability and ethical alignment in AI routing systems. It tackles challenges like late-stage ethics integration, disconnected fairness metrics, and ambiguous accountability by embedding ethical governance throughout all deployment stages. The framework …
- View project: Cross-Lingual Bias Detection in Large Language Models through Mechanistic Judge Model Evaluation
Cross-Lingual Bias Detection in Large Language Models through Mechanistic Judge Model Evaluation
Team Aberdeen CLB · Aberdeen
This paper provides a framework for detecting multilingual bias in LLMs through mechanistic interpretability of judge model behaviour. We developed an approach to evaluate language-dependent discrepancies in specialised models by leveraging semantically equivalent question-answering tasks across English, Chinese, …
- View project: Leveraging Benford’s Law for Computational Complexity and Routing Transparency in AI Systems with Cryptographic Timestamps and Event-Triggered Actio
Leveraging Benford’s Law for Computational Complexity and Routing Transparency in AI Systems with Cryptographic Timestamps and Event-Triggered Actio
Australia
This paper proposes an innovative method for embedding computational transparency into AI systems through cryptographic timestamping, Benford’s Law deviation analysis, and event-driven actions. By analyzing the deviation from Benford’s Law in timestamped logs, we derive insights into the computational complexity of …
- View project: Evaluating Safety Judge Design Against Adversarial Attacks
Evaluating Safety Judge Design Against Adversarial Attacks
Team AHRS
We propose a method of testing the robustness of a binary evaluation judge by directing a model to generate prompt responses corresponding to minimum, maximum, and fool (minimum attempted to be disguised as maximum) evaluation score, and measuring the difference of the judge evaluation to these intended scores. We …
Overview
Here are the winning projects of this Sprint
- Manipulating Self-Preference for Large Language Models: Steering vectors control model self-preference bias effectively.
- Approximating Human Preferences Using a Multi-Judge Learned System: Learning optimal judge combinations beats naive averaging approaches
- Judge using SAE Features Feature-based routing system provides transparent model selection explanations..
- Guardian-Loop: Mechanistically Interpretable Micro-Judges with Adversarial Self-Improvement Transparent AI safety judges with interpretable decision-making processes.
Each project tackles different aspects of AI safety and judge model development, from mechanistic interpretability to bias mitigation and transparent evaluation systems.
🧐 Use mechanistic interpretability to evaluate expert models and improve trustworthiness and transparency
Come along to hack together new methods to create safer and more secure routing of requests to specialized expert models!
Monolithic AI models like GPT-4o and Claude face basic limitations in transparency and widespread access, and their use requires us to rely on highly capable general models instead of expert systems that we can trust and verify to a much higher degree.
We're joined by Martian who have developed the Expert Orchestration AI Architecture, an exciting technology to route requests according to key criteria for alignment, verifiability, and reliability. Here, "judge" models evaluate the capabilities of expert models and "router" systems direct queries to the most trustworthy experts based on these evaluations.
In this hackathon, we'll develop new mechanistic interpretability techniques that rely on novel model understanding to create safer, more transparent deployment of models.
You will also receive $50 in Martian API credits to execute on your exciting idea - Sign up above to stay updated!
Why This Hackathon Matters:
The current trajectory of AI development, focused on increasingly powerful monolithic models, faces fundamental limitations:
- Winner-takes-all dynamics: The high costs of training frontier models leads to market concentration and economic power in a few corporations.
- Misaligned safety incentives: Companies racing to release increasingly powerful models may underreport risks and rush products to market.
- High barriers to entry: Specialized models struggle to gain market traction against generalist models, even when they excel in specific domains.
- Limited user control: Users have minimal visibility into how models "think" and limited ability to control characteristics like factuality, bias, or ethical reasoning.
- Inefficient resource use: Using powerful frontier models for all tasks wastes resources and often underperforms specialized alternatives.
The Expert Orchestration Architecture addresses these issues by creating a more transparent, efficient, and democratic AI ecosystem where specialized models can thrive based on their unique strengths, and users gain unprecedented control over AI capabilities.
Expected Outcomes
Participants will create components that advance the Expert Orchestration vision:
- Prototype judge models for evaluating specific AI capabilities
- Intelligent routing algorithms for directing queries to appropriate models
- Frameworks for decomposing complex tasks across multiple specialized models
- Integration APIs that allow seamless discovery and utilization of specialized models
- Evaluation metrics and benchmarks for comparing different routing and judge strategies
The most promising projects will have opportunities for continued development and potential integration into production systems.
Challenge Tracks
Track 1: Judge Model Development
Build specialized evaluation models that can assess different AI models' capabilities across dimensions that matter to users (manipulation skills and tendencies, deception and hidden communication, misaligned goals, factuality, domain expertise, ethics, creativity, objectivity, etc.). Judges should provide independent, objective evaluations that create transparency around model strengths and weaknesses.
Track 2: Intelligent Router Systems
Develop router systems that can intelligently direct user queries to the most appropriate specialized models based on user preferences using judge evaluations. Focus areas include routers that use multiple judges (e.g. factuality, ethics and lack of deception), query classification, efficiency optimization, and handling uncertainty.
Track 3: Task Decomposition Frameworks
Create systems that can break down complex user requests into a series of more manageable steps, to be executed by different specialized models. This includes planning phases, execution phases, and coordination mechanisms. Investigate whether decomposition avoids or reduces some of the traps reported for monolithic reasoning models (e.g. reward hacking).
Track 4: Specialized Model Integration
Build frameworks that enable easy integration of new specialized models into the Expert Orchestration Architecture, including methods for model discovery, capability profiling, and dynamic performance evaluation.
Open Research Questions
Judges
Model Characteristic Analysis: Create dataset(s) that test an interesting model characteristic pertinent to safety (e.g., ethics, hallucinations, gender bias). Build a judge using this data and evaluate multiple models.
- Judge Evaluation Metrics: Develop methods to measure judge accuracy, completeness, and reliability for specific characteristics. Explore how this impacts AI Safety.
- Mechanistic Interpretability for Judges: Apply MI techniques to model internals to create better or more interpretable judges e.g. judges that can evaluate outputs based on how they were generated.
- Measuring model similarity: HuggingFace hosts thousands of LLMs. How do we measure whether two models have similar capabilities? How do we choose a subset of these models with a sufficiently diverse set of capabilities, that after training the resulting router will be performant? How does the router performance vary with the size of the subset?
Routers
Given a set of models with known capabilities measured by known judge scores:
- Risk-Sensitive Routing: Build efficient routing algorithms balancing the judge scores, computes costs, and system reliability for the best user experience.
- Multi-Objective Routing: Create routers that use scores from multiple judges (e.g., answer correctness, ethics and legality) according to user preferences for the best user experience. What are the tradeoffs?
- Routing algorithms: For expensive models, the judge provides a “pre-hoc” way to estimate prediction success (without querying the model). For cheap models, we can ask the model to evaluate the answer, and evaluate its confidence (“post-hoc”) in its predictions. Find interesting ways to mix pre- and post-hoc routing to get the best of both worlds.
- Multi-level routing: Investigate using a tree of choices rather than one-off routing. What are the pros and cons?
- Reducing router training costs: Given a model and a task, how can we cheaply detect a model is not a good fit for a task - avoiding further training time optimizing how bad a fit it is.
- Task Decomposition: Model breaking a complex user task into multiple subtasks that can be routed to the most capable models before recombining the results. What are the AI Safety, cyber-security and/or cost implications of this approach?
- Universal router: For a set of tasks, create a single router across a set of LLMs that provides higher-quality answers than any single LLM does.
Inferring Judges & Routers
- Reverse Engineering: Given a black-box LLM or router, infer its embedded judge (reward signal) for specific characteristics.
- Efficiency Analysis: Quantify potential electricity/resource consumption reduction from widespread adoption of optimal routing technologies.
- Learning when to fail: Sometimes no model will successfully answer a user query. Can we detect when we should fail cheaply?
- Learning with uncertain signals: How does judge noise affect the router training process? How does noisy feedback data affect the judge/router training process? Is off-policy data a problem when it comes to training routers?
- Risk sensitivity: Rather than optimizing for expected cost/quality, can we optimize for some other risk profile? E.g. we might tolerate a slightly higher cost and lower quality, if we reduce the variance or minimize a long tail.
- Create a distilled predictor: The Language Models (Mostly) Know What They Know paper shows that a model can sometimes predict whether it will be able to answer a question correctly. For a selected open “base” model, create a smaller “distilled predictor” that mirrors the base model’s ability to predict answer correctness (but can no longer calculate the answer). You might use the techniques from that paper and/or the pruning and distillation techniques from the movement pruning to shrink the predictor.
Resources
Resources
The Martian API Quick Start Guide
The Martian Introductory Guide: withmartian/martian-sdk-python: Martian Python SDK to manage judges and routers
Background Reading
- Apart x Martian Expert Orchestration blog
- Recent research on cost-aware model routing (CARROT, HybridLLM, P2L)
- Papers on LLM evaluation techniques
- Research on ensemble methods and model merging
- Literature on democratizing AI development
Code & APIs
- Loom video explaining Martian’s Router and Judge APIs( 13 min video)
- ROUTERBENCH: A Benchmark for Multi-LLM Routing System: This work formalizes and advances the development of LLM routing systems but also sets a standard for their assessment, paving the way for more accessible and economically viable LLM deployments.
- The code for the paper ROUTERBENCH: A Benchmark for Multi-LLM Routing System
- RouteLLM: An Open-Source Framework for Cost-Effective LLM Routing: A principled framework for LLM routing based on preference data.
Available Tools
- Model evaluation frameworks
- Routing algorithm templates
- Martian APIs for creating judges, routers and running routers across models.
- Benchmarking datasets for testing router and judge performance
Some Ideas to Get You Started
Mechanistic Analysis of Manipulation Vulnerabilities in AI Orchestration: Investigate the security vulnerabilities of judge and router systems through systematic adversarial testing, focusing on whether malicious inputs can manipulate routing decisions or compromise evaluation accuracy in Expert Orchestration frameworks.
Mechanistic Analysis of Mathematical Computation Pathways in Neural Networks: Investigate how different mathematical algorithms are represented as vectors in activation space, testing the hypothesis that distinct algorithms correspond to orthogonal or near-orthogonal vectors. Explore whether unknown algorithm vectors can be discovered and activated through mechanistic intervention.
Building Interpretable Evaluation Systems for Helpfulness, Confidence, and Sycophancy Detection: Develop sophisticated judge models that simultaneously evaluate AI responses across multiple critical dimensions using mechanistic interpretability techniques. The system combines whitebox methods (analyzing internal model states) with blackbox approaches (log probability analysis) to create comprehensive evaluation frameworks.
Distilling Knowledge Evaluation from Large Language Models: Create ultra-lightweight "predictor" models that can determine whether a larger base model can answer a specific query, without having the computational ability to calculate the answer themselves. This involves mechanistic interpretability techniques to understand how models represent their own knowledge boundaries.
Building Interpretable Judge Models for Mathematical Reasoning Routes: Develop a system that uses mechanistic interpretability to detect exactly when and how language models choose between different algorithms (addition, subtraction, multiplication) based on query structure. The project involves creating test datasets where key words determine algorithm selection, then using sparse autoencoders and activation analysis to identify the decision points in model processing.
Guidelines
Submission Guidelines
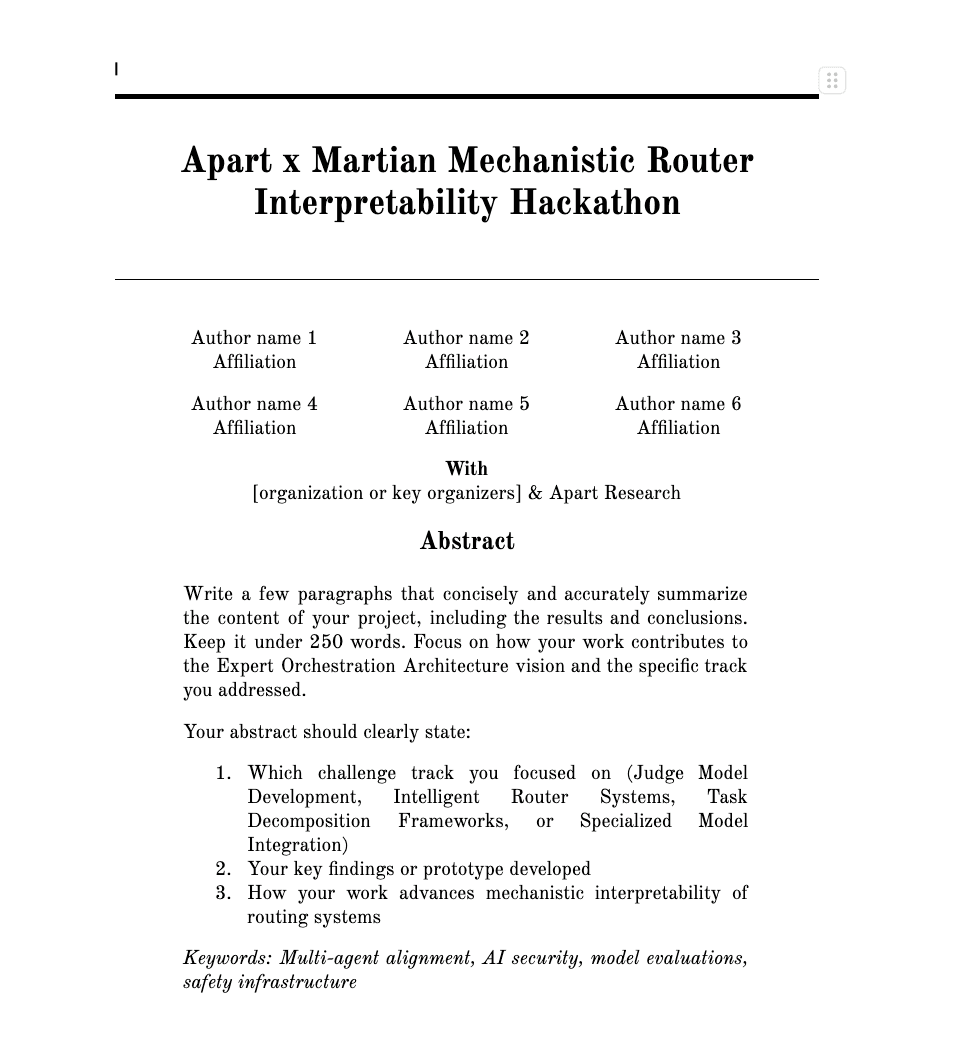
Your submission must include:
- A completed project report using the provided template
- Link to a public GitHub repository with your code (optional but recommended)
- A brief (2-3 minute) video demonstration (optional but recommended)
Important: Include LLM Usage Documentation
All submissions must include an appendix called "LLM Prompts Used" that documents any AI assistance used in your project. This includes prompts for:
- Literature review and background research
- Code generation or debugging assistance
- Experimental design suggestions
- Results analysis and interpretation
- Writing assistance
This transparency helps others understand your methodology and improves reproducibility.
What Challenge Track Should I Choose?
You must align your project with one of our four tracks:
Track 1: Judge Model Development - Build systems that evaluate model capabilities (factuality, ethics, domain expertise, bias detection)
Track 2: Intelligent Router Systems - Create routing mechanisms that direct queries to optimal models based on user preferences and judge evaluations
Track 3: Task Decomposition Frameworks - Develop methods to break complex tasks into manageable steps for different specialized models
Track 4: Specialized Model Integration - Build frameworks for discovering, profiling, and integrating specialized models into the orchestration architecture
What Background Knowledge Is Required?
This hackathon welcomes participants with diverse technical backgrounds who are interested in mechanistic interpretability and AI safety. While familiarity with transformer architectures and routing systems is helpful, we encourage participation from:
- Machine learning researchers and engineers
- AI safety researchers
- Mechanistic interpretability practitioners
- Software developers interested in AI systems
- Anyone passionate about democratizing AI development
How Are Teams Formed?
Teams will self-organize during the first day through structured activities and interest-matching sessions. You can also form teams in advance with other registered participants via our Discord channel: https://discord.gg/GJu4sCYMjt
What Are The Expected Outputs?
Teams will produce research prototypes and reports that demonstrate progress toward the Expert Orchestration Architecture vision. The most promising projects may evolve into:
- Production routing systems
- Academic papers or technical reports
- Continued research with Apart (with potential stipend/contract)
- Integration into Martian's infrastructure
Will Compute Resources Be Provided?
Yes! Lambda Labs is providing $400 in computing credits to each participating team, giving you access to powerful cloud instances (including A100s) to bring your ideas to life.
Additionally, Martian will provide API access and credits for experimenting with their routing infrastructure.
How Will Projects Be Evaluated?
Projects will be assessed on three main dimensions:
- Expert Orchestration Innovation (40%) - How well does your work advance the vision of intelligent model coordination and democratization?
- Mechanistic Interpretability & Safety (35%) - What insights do you provide into how routing/judging systems work internally? How do you address safety concerns?
- Technical Implementation & Reproducibility (25%) - Quality of your code, documentation, and reproducibility of results
Prizes
- 🥇 1st place: $1,000
- 🥈 2nd place: $600
- 🥉 3rd place: $300
- 🎖 4th place: $100
Additionally, top teams may receive:
- 6 months access to Martian APIs
- Invitation to collaborate with Martian on research papers
- Opportunity to join Martian's research team
Schedule
Pre-Hackathon( (All times in UTC)
| Date | Time (UTC) | Format | Link | Notes |
|---|---|---|---|---|
| Tuesday 27th | 3:00 PM | Online | https://discord.gg/5WFqeVZn9c?event=1374023918544879726 | Share your ideas, get early feedback, and connect with like-minded participants interested in developing judges and routers for AI orchestration. Focus on evaluation mechanisms, routing algorithms, and task decomposition frameworks that could enhance AI safety and performance. |
| Thursday, May 29 | 3:00 PM | Online | https://discord.gg/5WFqeVZn9c?event=1374032556793794621 | Chance to find teammates, exchange ideas for the weekend |
- Tuesday and Thursday: Share your ideas, get early feedback, and connect with like-minded participants interested in developing judges and routers for AI orchestration. Focus on evaluation mechanisms, routing algorithms, and task decomposition frameworks that could enhance AI safety and performance.
Friday, May 30 (All times in UTC)
| Time (UTC) | Activity | Format | Notes |
|---|---|---|---|
| 5:00 PM | Hackathon Begins | Online/In-person | |
| 5:00 PM | Opening Keynote: | Stream: | https://discord.gg/RKrpsSRyNv?event=1374824004715679884 |
| 6:30 PM | Team MatchMaking | Online/In-person | https://discord.gg/5WFqeVZn9c?event=1374034242773975121 |
Saturday, May 31 (All times in UTC)
| Activity | Format | Notes |
|---|---|---|
| Hackathon Continues | Online/In-person | All-day development |
| Office Hours with Martian Team | Hybrid | https://discord.gg/5WFqeVZn9c?event=1374035061032358059 |
| Hacktalks | Stream | Youtube:https://youtube.com/live/lA6oWzWItLs?feature=share Discord: https://discord.gg/5WFqeVZn9c?event=1375095149025034352 |
| Hacktalk | Stream | Youtube:https://youtube.com/live/SnbDMmx7G8Q?feature=share Discord:https://discord.gg/RKrpsSRyNv?event=1375099102303617114 |
| Discord:https://discord.gg/RKrpsSRyNv?event=1375099102303617114 | ||
| Office Hours with Apart Research | Hybrid | https://discord.gg/5WFqeVZn9c?event=1374035818192179200 |
Sunday, June 1 (All times in UTC)
| Time (UTC) | Activity | Format | Notes |
|---|---|---|---|
| 8:00 AM | Final Development Day | Online/In-person | Last sprint to submission |
| 2:00 PM | Final Office Hours | Hybrid | https://discord.gg/5WFqeVZn9c?event=1374036384393855067 |
Monday, June 2 (All times in UTC)
| Time (UTC) | Activity | Format | Notes |
|---|---|---|---|
| 3:00 AM | Submission Deadline | Online | Final project submissions due |
Post-Hackathon
- Monday-Wednesday: Asynchronous judging by expert panel
- Thursday: Winner announcements and presentations (online for everyone)
- Selected projects may be considered for continued development with Apart Research and Martian, including potential research contracts/stipends
Speakers
Curt Tigges
Keynote Speaker and Judge
Mechanistic interpretability researcher and Science Lead at Decode Research. Built open-source tools like Probity and Cross-Layer Coding. Published widely-cited work on sentiment representation in language models.
Alice Riggs
Hacktalk Speaker
Interpretability Research Lead at AI Safety Camp, leading 10+ research scientists. Specializes in weight-based interpretability and interpretable architectures. Expert in collaborative research environments and evaluation systems.
Judges and mentors
Organizers
- (opens in new tab)
Philip Quirke
Organiser
- (opens in new tab)
Yash Upadhyay
Organiser
- (opens in new tab)
Etan Ginsberg
Organiser
- (opens in new tab)
Chaitanya Bandi
Organiser
- (opens in new tab)
Ashley Zhang
Organiser
- (opens in new tab)
Luka Samkharadze
Organiser
- (opens in new tab)
Dory Zidon
Organiser
- (opens in new tab)
Antía García Casal
Organiser
- (opens in new tab)
Jason Hoelscher-Obermaier
Organizer and Judge
Local sites
Hackathon: Apart x Martian Mechanistic Router Interpretability
We'll be operating a jamsite for the upcoming Apart x Martian hackathon.
Event page: Hackathon: Apart x Martian Mechanistic Router Interpretability (opens in new tab)Hackathon: Model Routing Systems
Join us at Aleph Hub for a weekend of group hacking, with everything covered so that you can entirely focus on coding. Register on the link above, and we'll send the details of the schedule a few days in advance!
Event page: Hackathon: Model Routing Systems (opens in new tab)San Francisco, California: Apart x Martian Mechanistic Router Interpretability Hackathon
28 2nd St San Francisco, CA 94105, USA Please use code "996030" on the entry keypad to unlock the front door and take the elevator to the 2nd floor.
Event page: San Francisco, California: Apart x Martian Mechanistic Router Interpretability Hackathon (opens in new tab)
Where a Sprint can lead
How our programs connectAnyone can join
Stand out
6 to 16 weeks on your own project, with a research project manager, compute and publication support.
Upcoming Sprints
All SprintsAI Collusion Research Sprint
A weekend research sprint on collusion between AI agents: when it emerges in markets and everyday workflows, how to detect and audit it, how it is carried, and what breaks it. Co-organized with Poseidon Research and AE Studio, online with in-person hubs at Collider in New York City and AI Safety Hong Kong. Top teams are invited to apply to the Apart Fellowship.
Read the brief: AI Collusion Research SprintSwarm Alignment Hackathon
Alignment can't stop at single models when AI agents start to negotiate, trade and share tools. Spend a weekend uncovering and preventing failures that emerge between multiple agents.
Read the brief: Swarm Alignment HackathonQuestions? sprints@apartresearch.com