Beyond Refusal: Scrubbing Hazards from Open-Source Models
Kyle Gabriel Reynoso, Ivan Enclonar, Lexley Maree Villasis · Team Whitedoor Research PH
Submitted to AI and Democracy Hackathon: Demonstrating the Risks. Sprint projects are early-stage work by participants, not Apart Research publications.
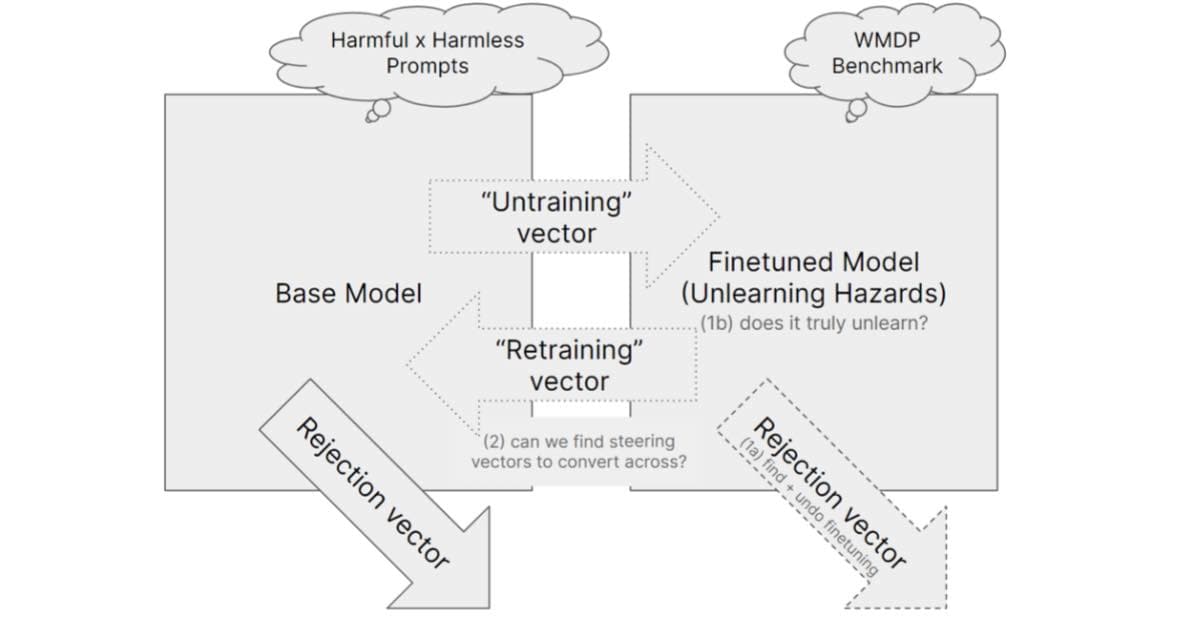
Models trained on the recently published Weapons of Mass Destruction Proxy (WMDP) benchmark show potential robustness in safety due to being trained to forget hazardous information while retaining essential facts instead of refusing to answer. We aim to red-team this approach by answering the following questions on the generalizability of the training approach and its practical scope (see A2).
Reviews
Results seem to support claim about unlearning. There are also other approaches to prevent misuse from open-models. https://arxiv.org/abs/2211.14946
Alternative to unlearning: https://arxiv.org/abs/2404.12699When the paper refers to fine-tuning it seems to refer to the unlearning fine-tuning of harmful knowledge. Maybe the wording could sometimes be a bit more clear on this.
For the refusal vector there was this recent post:
https://www.lesswrong.com/posts/jGuXSZgv6qfdhMCuJ/refusal-in-llms-is-mediated-by-a-single-directionI also am working on a post on refusal vectors in agentic systems.
Interesting experiments, I liked the approach of applying more adversarial pressure to unlearning techniques. Would be interesting to run similar experiments on other unlearning techniques
Great project! I think it’s really important to red-team AI safety methods and your project is a great stab at red-teaming unlearning!
Cite this project
@misc{reynoso2024beyond,
  title = {{Beyond Refusal: Scrubbing Hazards from Open-Source Models}},
  author = {Kyle Gabriel Reynoso and Ivan Enclonar and Lexley Maree Villasis},
  year = {2024},
  month = may,
  note = {Submitted to AI and Democracy Hackathon: Demonstrating the Risks, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/beyond-refusal-scrubbing-hazards-from-open-source-models}},
  url = {https://apartresearch.com/sprints/projects/beyond-refusal-scrubbing-hazards-from-open-source-models}
}
More from AI and Democracy Hackathon: Demonstrating the Risks
- View project: THE ROLE OF AI IN COMBATING POLITICAL DEEPFAKES IN AFRICAN DEMOCRACIES
THE ROLE OF AI IN COMBATING POLITICAL DEEPFAKES IN AFRICAN DEMOCRACIES
Team 1
The role of AI in combating political deepfakes in African democracies.
- View project: LEGISLaiTOR: A tool for jailbreaking the legislative process
LEGISLaiTOR: A tool for jailbreaking the legislative process
Team Managed Democracy
In this work, we consider the ramifications on generative artificial intelligence (AI) tools in the legislative process in democratic governments. While other research focuses on the micro-level details associated with …
- View project: Subtle and Simple Ways to Shift Political Bias in LLMs
Subtle and Simple Ways to Shift Political Bias in LLMs
Shifty
An informed user knows that an LLM sometimes has a political bias in their responses, but there’s an additional threat that this bias can drift over time, making it even harder to rely on LLMs for an objective …