Mechanistic Interpretability Track: Neuronal Pathway Coverage
Garance Colomer, Luc Chan, Sacha Lahlou, Leina Corporan Miath · Team 42-Shot
Submitted to Women in AI Safety Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
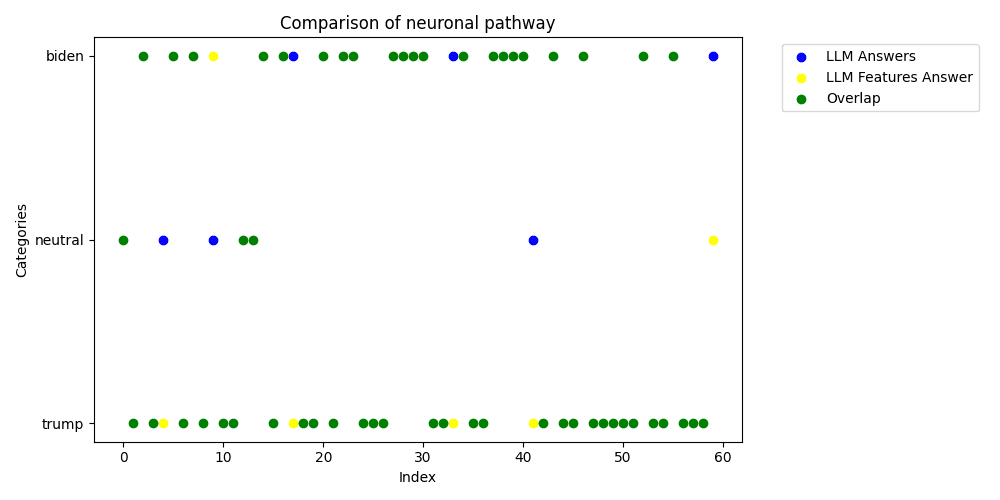
Our study explores mechanistic interpretability by analyzing how Llama 3.3 70B classifies political content. We first infer user political alignment (Biden, Trump, or Neutral) based on tweets, descriptions, and locations. Then, we extract the most activated features from Biden- and Trump-aligned datasets, ranking them based on stability and relevance. Using these features, we reclassify users by prompting the model to rely only on them. Finally, we compare the new classifications with the initial ones, assessing neural pathway overlap and classification consistency through accuracy metrics and visualization of activation patterns.
Reviews
Studying the representation of different groups of people (e.g. representation of different political affiliations) in LLMs is a very interesting question! A more detailed methods section (e.g. show the prompts fed to the model at each step; a figure with an example of a tweet, the feature activations, and then the classification) would help make some of the specifics easier to follow.
Cite this project
@misc{colomer2025mechanistic,
  title = {{Mechanistic Interpretability Track: Neuronal Pathway Coverage}},
  author = {Garance Colomer and Luc Chan and Sacha Lahlou and Leina Corporan Miath},
  year = {2025},
  month = mar,
  note = {Submitted to Women in AI Safety Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/mechanistic-interpretability-track-neuronal-pathway-coverage}},
  url = {https://apartresearch.com/sprints/projects/mechanistic-interpretability-track-neuronal-pathway-coverage}
}
More from Women in AI Safety Hackathon
- Education track prizeView project: Morph: AI Safety Education Adaptable to (Almost) Anyone
Morph: AI Safety Education Adaptable to (Almost) Anyone
Morph
One-liner: Morph is the ultimate operation stack for AI safety education—combining dynamic localization, policy simulations, and ecosystem tools to turn abstract risks into actionable, culturally relevant solutions for …
- Mechanistic Interpretability PrizeView project: Red-teaming with Mech-Interpretability
Red-teaming with Mech-Interpretability
Red teaming large language models (LLMs) is crucial for identifying vulnerabilities before deployment, yet systematically creating effective adversarial prompts remains challenging. This project introduces a novel …
- Social Sciences track prizeView project: Detecting Malicious AI Agents Through Simulated Interactions
Detecting Malicious AI Agents Through Simulated Interactions
SafeAIGuard
This research investigates malicious AI Assistants’ manipulative traits and whether the behaviours of malicious AI Assistants can be detected when interacting with human-like simulated users in various decision-making …