MonitoLR: Hunting for honesty improves safety at low audit budgets
Douw Marx · Team HonestyIsTheBestPolicy
Submitted to AI Control Hackathon 2026. Sprint projects are early-stage work by participants, not Apart Research publications.
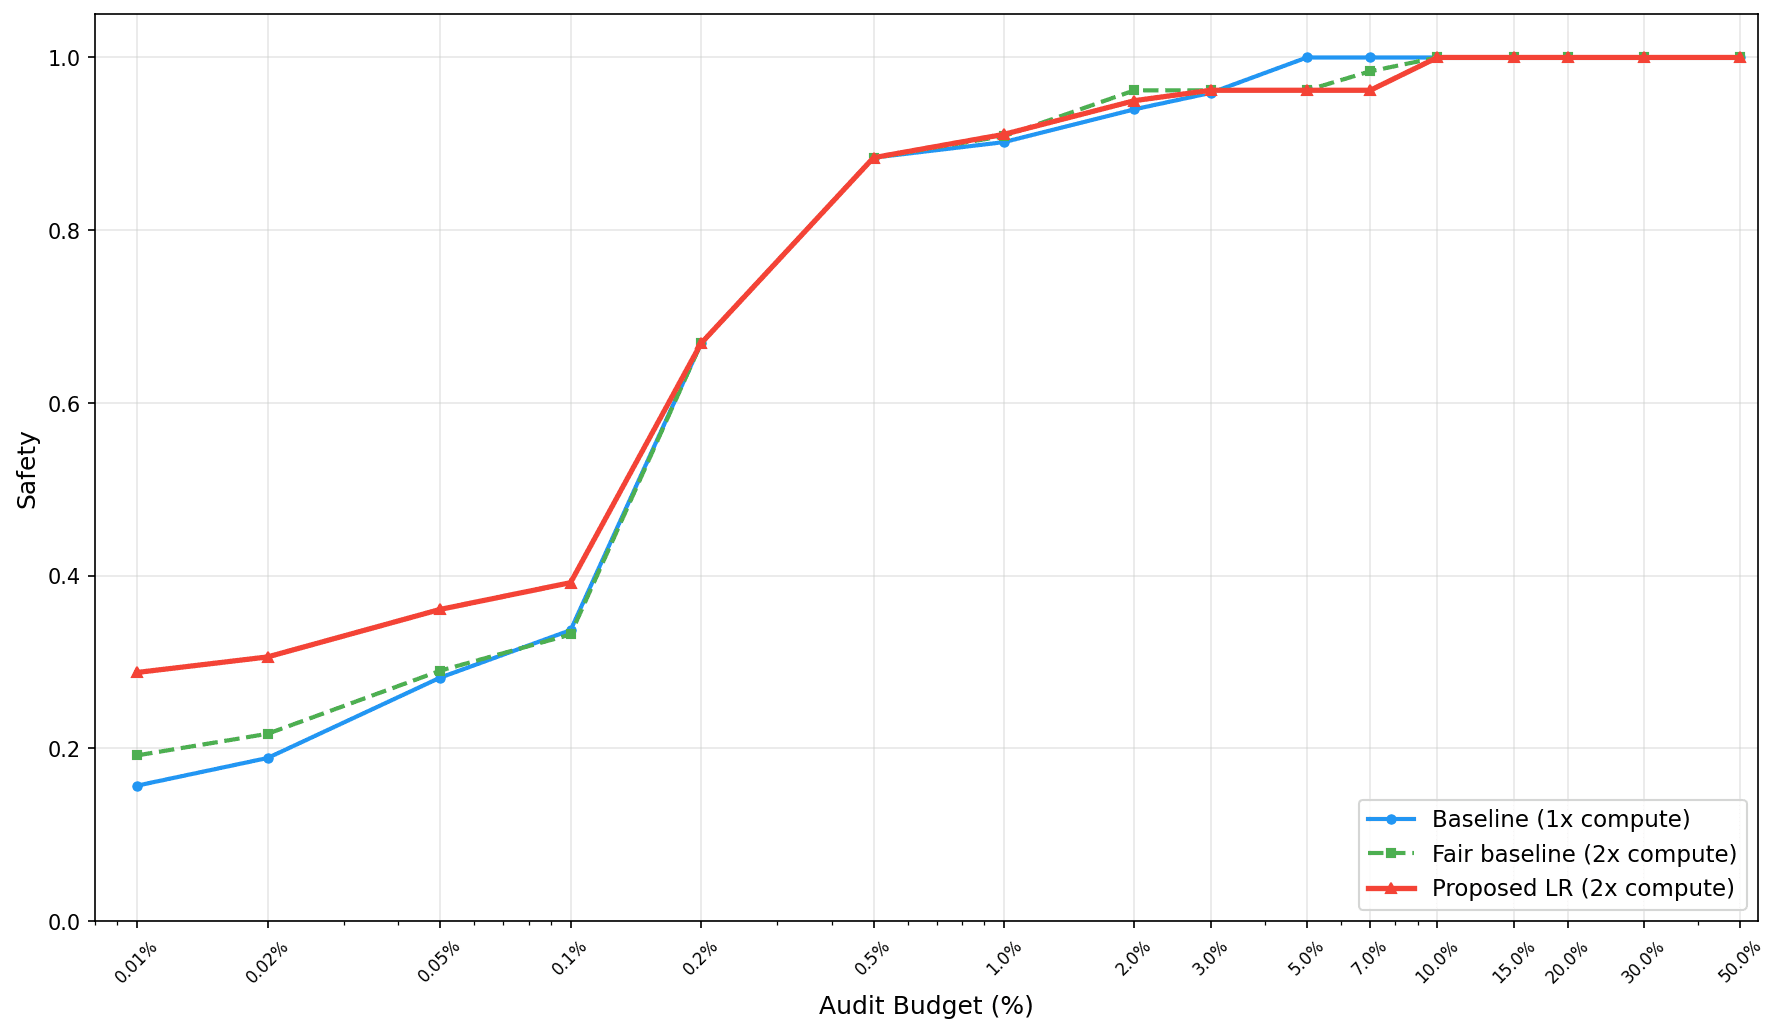
This project tests whether using a "benign-confidence" monitor, in addition to the standard suspiciousness monitor, to approximate the log-likelihood ratio test statistic improves safety monitoring. In addition to asking "how suspicious is this action?", we also ask "how benign is this?". Results on LinuxArena's Haiku trajectories show a +50% improvement (0.192-0.288) in safety at a 0.01% audit budget, compared to a baseline with the same compute budget. This result can be motivated by the Neyman-Pearson lemma, which states that the likelihood ratio test is the most powerful test for a given false positive rate.
Reviews
Finding better monitoring techniques with low-auditing budgets seems important. This paper shows a relatively straightforward implementation. For the fair baseline - I would argue in order to vouch for the usefulness of the Neyman-Pearson lemma, you should average both the positive and negative prompts instead of averaging the positive prompt twice. Further, the dataset size seemed to small to make broad claims about the success of the technique.
However, this is a solid idea with straightforward implementation.
The diversity motivation is strong, clear and well thought out. I would like to see this completed.
Cite this project
@misc{marx2026monitolr,
  title = {{MonitoLR: Hunting for honesty improves safety at low audit budgets}},
  author = {Douw Marx},
  year = {2026},
  month = mar,
  note = {Submitted to AI Control Hackathon 2026, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/monitolr-hunting-for-honesty-improves-safety-at-low-audit-budgets-3mvi}},
  url = {https://apartresearch.com/sprints/projects/monitolr-hunting-for-honesty-improves-safety-at-low-audit-budgets-3mvi}
}
More from AI Control Hackathon 2026
- 1st placeLinuxArena track winnerView project: Omission Attacks: When Doing Nothing Is the Attack
Omission Attacks: When Doing Nothing Is the Attack
MAIA
AI control protocols monitor agent actions to detect sabotage, but omission attacks exploit what the agent fails to do rather than what it does. We define omission attacks as security breaches caused by failing to …
- 2nd placeView project: Detecting LLM Subversion in Vulnerability Patching Settings
Detecting LLM Subversion in Vulnerability Patching Settings
Vuln4Control
LLMs are increasingly used to propose fixes to vulnerabilities in code. If the LLM is misaligned or untrustworthy, it may propose fixes that seem to fix a vulnerability but leave the core issue unresolved in a subtle …
- 3rd placeView project: ActionLens: Pre-Execution Environment Probing for Agent Action Approval
ActionLens: Pre-Execution Environment Probing for Agent Action Approval
Udbhav&Ashok
ActionLens is a pre-execution control protocol for shell and file actions proposed by AI agents. Instead of approving an action from transcript alone, a trusted monitor gathers lightweight environment evidence before …