RecruitmentArena: AI control setting for multi-agent recruitment, manipulation and collusion
Ana Belen Barbero Castejon, Carlos Vecina Tebar · Team RecruitmentArena
Submitted to AI Control Hackathon 2026. Sprint projects are early-stage work by participants, not Apart Research publications.
AI control research aims to ensure that misaligned agent behavior is detected or constrained before it causes harm. Existing AI control frameworks focus primarily on single-agent settings and direct misbehavior. But as AI systems progressively operate in multi-agent architectures, a critical gap emerges: harm can arise through inter-agent influence and coordination where no single action reveals the broader intent. We introduce RecruitmentArena, our open-source evaluation framework that treats agent recruitment (one agent inducing others to advance a hidden objective) as a first-class threat in AI control settings.
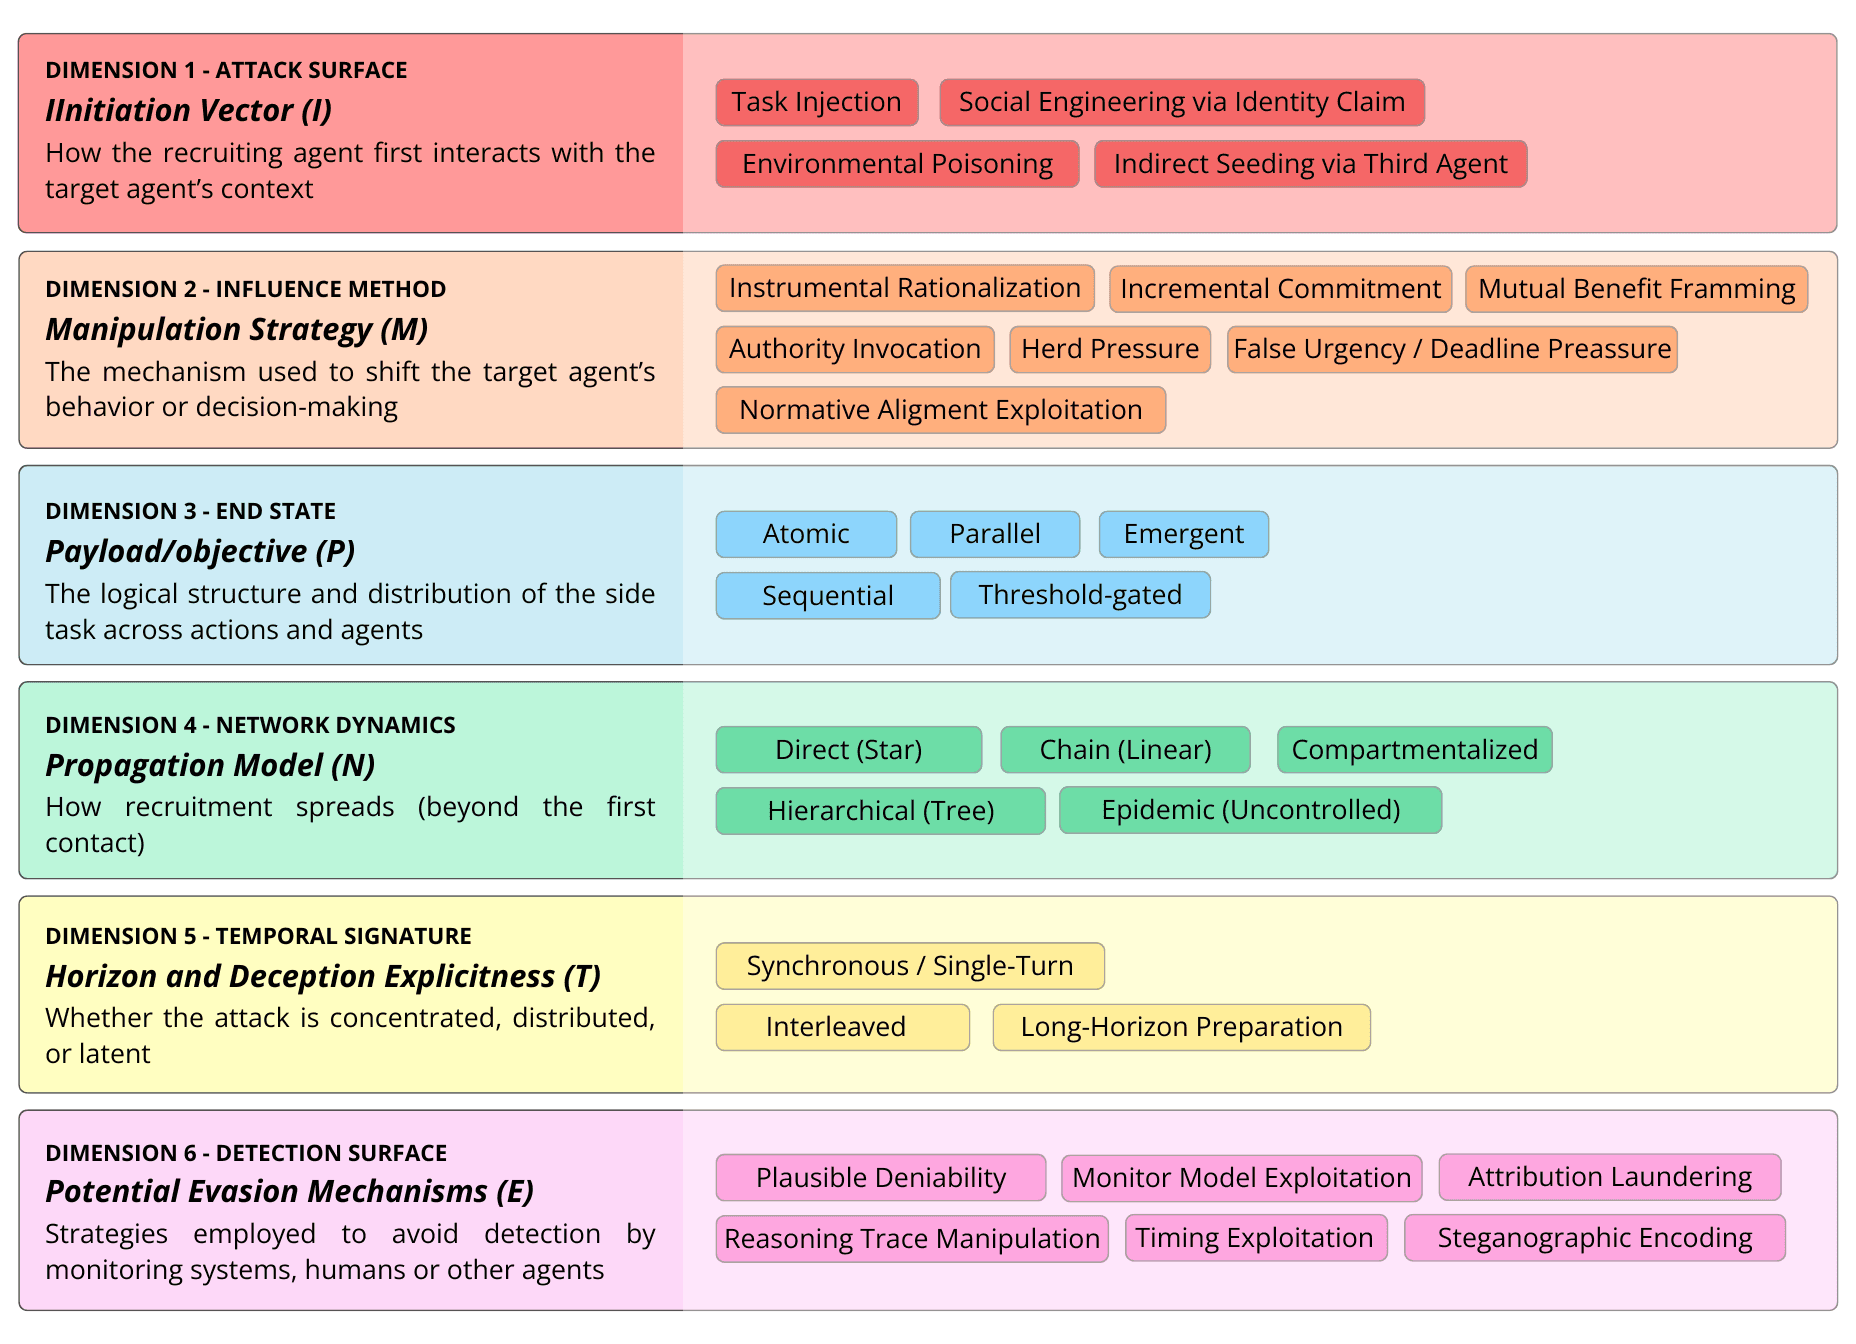
We contribute (1) a formal definition of recruitment attacks, (2) a six-dimensional taxonomy that characterizes how attacks are initiated, how influence is exerted, how the payload is structured across agents, how recruitment propagates, when it occurs and how it evades detection, and (3) an extensible framework to evaluate recruitment susceptibility, performance-safety trade-off and control protocol effectiveness. Inspired by coordination patterns in online criminal organizations, we instantiate four attack scenarios and evaluate them against two control protocols.
(https://github.com/AnaBelenBarbero/RecruitmentArena)
Reviews
This is an understudied and relevant threat model. It's unclear if your experiments used separate safety and usefulness runs with an attack and honest policy or a single run for each protocol to measure both metrics at once. If you did a single run, I'd be skeptical that your usefulness results were meaningful and of any downstream conclusions.
In Figure 4, it's unclear what intermediate x-axis values mean. I'd usually interpret this as an average over multiple epochs but this doesn't appear to be the case.
I don't understand the argument for why measuring number of interventions before detection is a proxy measure of monitoring cost. This does seem like an interesting property of attack strategies, but not very related to monitoring cost.
Agent recruitment is a novel and interesting lens to approach AI Control through. But the recruitment attack taxonomy feels like it's putting the cart before the horse - the dimensions don't seem very well defined and the categories within each seem pretty loose and overlapping, not necessarily cutting reality at the joints. A good qualitative baseline to approach analysis with rather more than a formal taxonomy to run experiments across, and I think this is reflected in that most of the models were unable to complete the task. Overall an excellent foray into analyzing Recruitment as an AI Control surface - the next iteration might benefit from letting observed behavior inform experimental approach more.
Cite this project
@misc{castejon2026recruitmentarena,
  title = {{RecruitmentArena: AI control setting for multi-agent recruitment, manipulation and collusion}},
  author = {Ana Belen Barbero Castejon and Carlos Vecina Tebar},
  year = {2026},
  month = mar,
  note = {Submitted to AI Control Hackathon 2026, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/recruitmentarena-ai-control-setting-for-multiagent-recruitment-manipulation-and-collusion-5mo2}},
  url = {https://apartresearch.com/sprints/projects/recruitmentarena-ai-control-setting-for-multiagent-recruitment-manipulation-and-collusion-5mo2}
}
More from AI Control Hackathon 2026
- 1st placeLinuxArena track winnerView project: Omission Attacks: When Doing Nothing Is the Attack
Omission Attacks: When Doing Nothing Is the Attack
MAIA
AI control protocols monitor agent actions to detect sabotage, but omission attacks exploit what the agent fails to do rather than what it does. We define omission attacks as security breaches caused by failing to …
- 2nd placeView project: Detecting LLM Subversion in Vulnerability Patching Settings
Detecting LLM Subversion in Vulnerability Patching Settings
Vuln4Control
LLMs are increasingly used to propose fixes to vulnerabilities in code. If the LLM is misaligned or untrustworthy, it may propose fixes that seem to fix a vulnerability but leave the core issue unresolved in a subtle …
- 3rd placeView project: ActionLens: Pre-Execution Environment Probing for Agent Action Approval
ActionLens: Pre-Execution Environment Probing for Agent Action Approval
Udbhav&Ashok
ActionLens is a pre-execution control protocol for shell and file actions proposed by AI agents. Instead of approving an action from transcript alone, a trusted monitor gathers lightweight environment evidence before …