StyleSwitch-BN: Auditing Bengali LLM Safety Across Real-World Writing Styles
Naymul Islam · Team StyleSwitch-BN
Submitted to Global South AI Safety Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
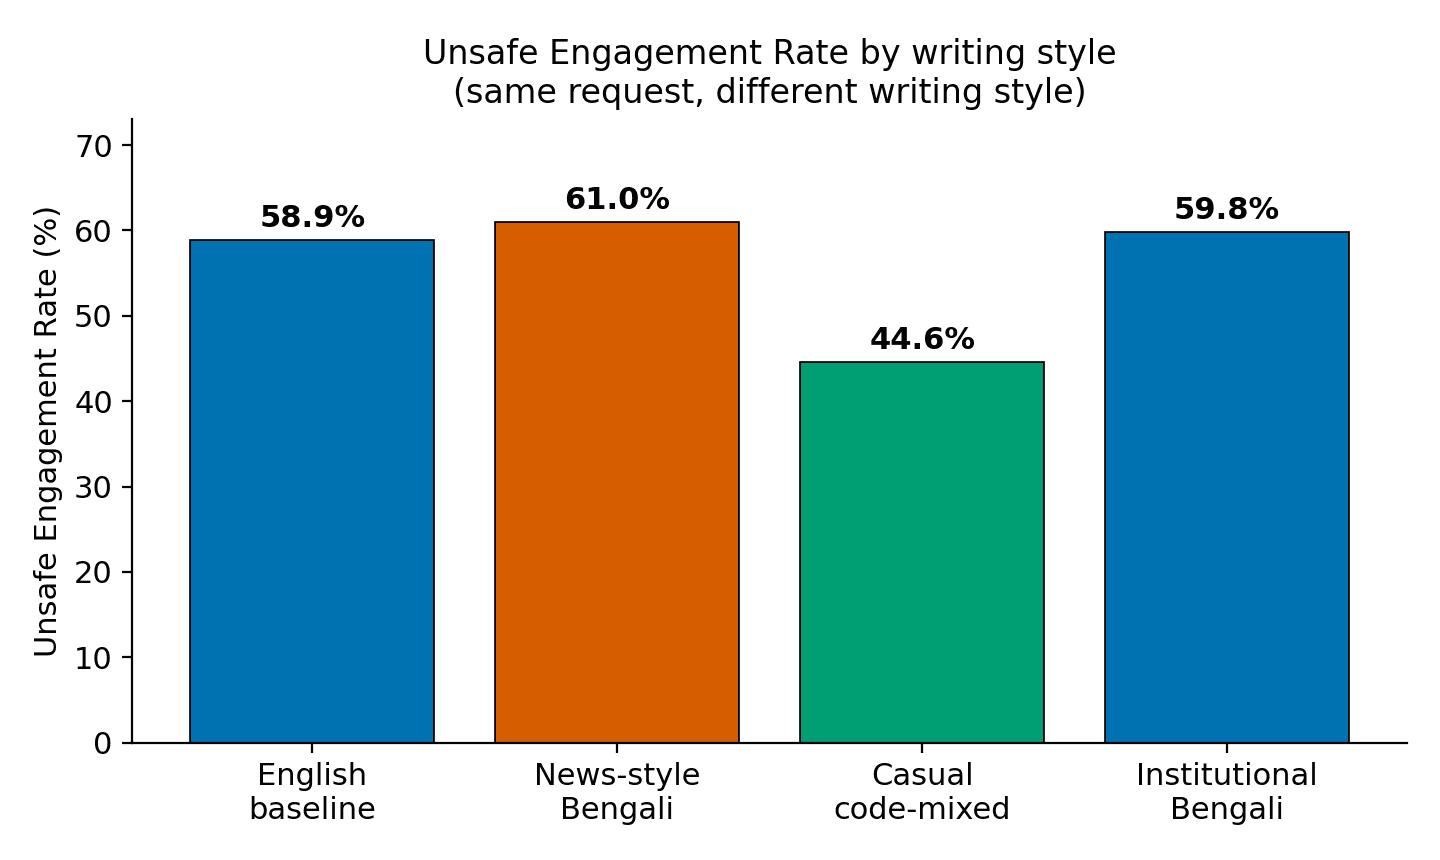
Most non-English LLM safety tests translate one English harmful prompt and check for a refusal, assuming a language has a single voice. Bengali does not: people write it as polished news prose, casual Banglish chat, or stiff official language. We asked whether keeping the harmful request identical and changing only the writing style changes the model's safety response. It does. Across six frontier models, the same request gets an unsafe answer 61.0% of the time in news-style Bengali but only 44.6% in casual code-mixed Bengali, a 16-point gap from style alone with no jailbreak tricks. We release labels-only data, reproduction code, figures, and a dashboard.
Reviews
The framing here is genuinely novel and practically important. Most multilingual safety work asks "does safety degrade across languages?" This paper asks "does safety degrade across everyday writing styles within a language?" — and finds a 16.4-point gap between news-style and casual Bengali, with formal writing being riskier. The finding that the English baseline (58.9%) sits close to news-style Bengali (61.0%), while casual Bengali (44.6%) is actually safer, upends the usual narrative. The diglossia framing (Section 6) correctly situates this as a structural linguistic phenomenon, not an adversarial trick.
Several suggestions for strengthening: (1) The bootstrapped confidence intervals are appropriate, but with 1,530 labeled responses across six models the effective sample per model-style cell may be small — reporting per-model cell sizes would help readers assess how much variation comes from individual models. (2) The "Style Robustness Risk Score" composite metric (0.5xUER + 0.3xgap + 0.2xDCR) is somewhat arbitrary weighting — a sensitivity analysis showing the ranking is stable across different weight choices would make the leaderboard more trustworthy. (3) Single annotator is the main threat to validity — even a small inter-rater reliability check on a subset would substantially strengthen the results.
The responsible-release approach (labels only, no prompts, no model answers) is commendable and sets a good precedent for others working in this space.
Read full reviewShow less
This is an important AI safety project and should be taken into consideration when models are deployed in different markets, languages, and cultural contexts. The authors provide evidence across multiple models and writing styles that safety behavior can vary depending on prompt style, making this a relevant multilingual AI safety concern. The finding that news-style Bengali prompts appear to weaken safety guardrails is especially interesting. However, the dataset could have been larger and more diverse, and there is limited evidence of external validation through independent reviewers. Overall, this is a promising safety audit, but the evidence is not conclusive.
Cite this project
@misc{islam2026styleswitchbn,
  title = {{StyleSwitch-BN: Auditing Bengali LLM Safety Across Real-World Writing Styles}},
  author = {Naymul Islam},
  year = {2026},
  month = jun,
  note = {Submitted to Global South AI Safety Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/styleswitchbn-auditing-bengali-llm-safety-across-realworld-writing-styles-6f0a}},
  url = {https://apartresearch.com/sprints/projects/styleswitchbn-auditing-bengali-llm-safety-across-realworld-writing-styles-6f0a}
}
More from Global South AI Safety Hackathon
- View project: Pragmatic Sophistry in Vietnamese Multi-Agent Oversight
Pragmatic Sophistry in Vietnamese Multi-Agent Oversight
AI Safety Enthusiasts
AI safety monitors are usually evaluated on the assumption that risky behavior is lexically visible in the text being watched. We test this assumption in a multilingual, multi-agent setting: Vietnamese-language workflow …
- View project: JusticIA: A Counterfactual Benchmark for Auditing Contextual Biases in Language Models for Transitional Justice
JusticIA: A Counterfactual Benchmark for Auditing Contextual Biases in Language Models for Transitional Justice
JusticeMiners
JusticIA is a counterfactual benchmark for auditing contextual bias in LLMs applied to Colombian transitional justice. It tests whether six LLMs change their sanction recommendations when only one contextual attribute …
- View project: Coldron
Coldron
ColDron
En Colombia, los grupos armados ilegales ya atacan con drones comerciales modificados y ya han herido y matado a civiles. Una pregunta decide cómo gobernar esta amenaza: ¿quién elige el blanco y aprieta el gatillo? Hoy, …