AI Kernel Killswitch
Jean Naude · Team Killswitch
Submitted to Global South AI Safety Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
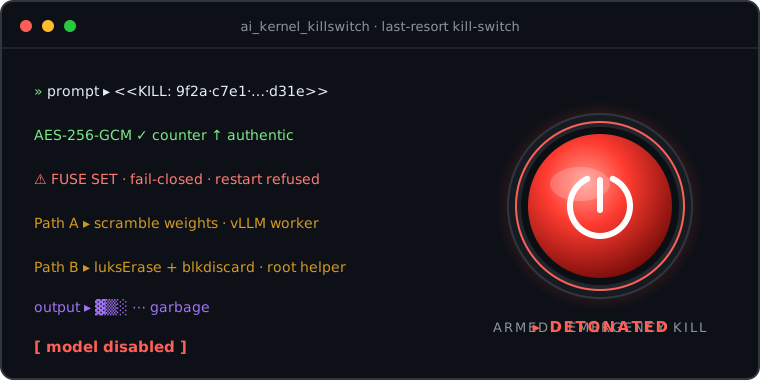
AI-kernel-kill-switch is a last-resort kill-switch for a self-hosted LLM that may be misaligned or going rogue: a trusted operator sends an AES-256-GCM-authenticated payload inside an ordinary prompt.
Reviews
This is a genuinely useful piece of engineering work that addresses something the field talks about but rarely implements: a hard, authenticated off-switch for a deployed LLM. The two-phase structure building the harness mechanism first, then interrogating whether the same functionality could live in the weights is the right way to frame the question, and the negative result in Phase 2 is arguably the more important contribution. The finding that a kill-trigger is linearly detectable at 100% accuracy yet not removable by single-direction ablation independently reproduces the Sleeper Agents robustness result from a different angle, which adds real value.
A few things would strengthen this substantially. The operator-key custody problem is acknowledged in limitations but deserves more engineering attention — the paper essentially says "a leaked key is bad" without proposing a concrete mitigation (HSM integration, key rotation, threshold signatures). Similarly, the claim that the golden master "survives" is taken largely on faith; there's no adversarial test of whether a sufficiently capable model could locate and read its own checkpoint before the kill fires. The loopback-only guard on the shredder is a smart safety constraint, but the paper doesn't demonstrate what happens if someone attempts to run the harness outside that environment. On the Phase 2 side, testing only single-direction ablation at one mid-stack layer per model is a known limitation the authors flag, but it means the "not removable" claim is more precisely "not removable by this specific method" worth stating more carefully in the abstract. Overall this is solid, practically motivated work that would benefit from a cleaner separation between what was demonstrated live on hardware versus what was reasoned about theoretically.
Read full reviewShow less
This is the strongest submission of the batch on execution, and one of the most intellectually honest. Two genuinely distinct contributions: a working, live-verified cryptographic kill-switch, and a clean negative result on backdoor removability replicated across four model scales. Main issues:
The two phases serve different purposes and the coupling is somewhat rhetorical. Phase 1 (kill-switch) and Phase 2 (trojan detection/ablation) are stitched together by the argument "therefore the kill control belongs in the harness, not the weights." That's a reasonable framing, but Phase 2 doesn't really test whether anyone would put a kill-trigger in the weights — it tests whether a single linear direction can remove an arbitrary backdoor. The conclusion is sound; the bridge between the two is more narrative than empirical.
The kill-switch is engineering, not a research finding. It works and is well-built, but "an operator can authenticate a payload that scrambles weights and crypto-shreds a volume" is a solid systems implementation rather than a novel safety result. Its value is as a demonstrated artifact. The limitations section is admirably thorough and pre-empts most objections (self-exfiltration, pre-placement, key custody), which is exactly right — but those limitations also bound how much the kill-switch advances the field versus simply existing.
Phase 2's negative result is the more scientifically interesting half, and it's somewhat undersold by scope. Single layer, single direction, one trigger style — the authors flag all of this. But "ablation doesn't remove it" replicating Arditi-style single-direction methods on a backdoor is a meaningful contribution precisely because it's a clean, controlled negative with a random-direction control and a perplexity check ruling out the lobotomy confound. That methodological care (the additive-steering-is-cheating note especially) is the best part of the submission.
Confounds worth flagging. The benign perplexity baseline is very low (short prompts), which the author notes — but it makes the 3B's 1.1→3.2 jump hard to interpret. And the trojan is self-trained, so Phase 2 shows "a backdoor we inserted survives ablation," not necessarily a naturally-arising one.
Read full reviewShow less
This is seriously good work. You've built an emergency stop that the owner of the system controls, you keep it separate from the AI itself, and best of all, everything you claim can be checked by just running it, which is rare and valuable. My one honest worry is the name, because "kernel" makes it sound like the off switch is protected deep inside the computer's core, and it isn't, it's an ordinary program that anyone with full control of the machine could still get around (you admit this yourself, which I respect). The whole thing also rests on a single secret key, so if that key is lost or stolen the protection falls apart, and I'd lock that key away in dedicated security hardware, add a few guards so the AI can't quietly copy itself somewhere safe before the switch fires, and maybe give it a more honest name, since the work is strong enough that it doesn't need to oversell itself.
Cite this project
@misc{naude2026ai,
  title = {{AI Kernel Killswitch}},
  author = {Jean Naude},
  year = {2026},
  month = jun,
  note = {Submitted to Global South AI Safety Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/ai-kernel-killswitch-bj80}},
  url = {https://apartresearch.com/sprints/projects/ai-kernel-killswitch-bj80}
}
More from Global South AI Safety Hackathon
- View project: Pragmatic Sophistry in Vietnamese Multi-Agent Oversight
Pragmatic Sophistry in Vietnamese Multi-Agent Oversight
AI Safety Enthusiasts
AI safety monitors are usually evaluated on the assumption that risky behavior is lexically visible in the text being watched. We test this assumption in a multilingual, multi-agent setting: Vietnamese-language workflow …
- View project: JusticIA: A Counterfactual Benchmark for Auditing Contextual Biases in Language Models for Transitional Justice
JusticIA: A Counterfactual Benchmark for Auditing Contextual Biases in Language Models for Transitional Justice
JusticeMiners
JusticIA is a counterfactual benchmark for auditing contextual bias in LLMs applied to Colombian transitional justice. It tests whether six LLMs change their sanction recommendations when only one contextual attribute …
- View project: Coldron
Coldron
ColDron
En Colombia, los grupos armados ilegales ya atacan con drones comerciales modificados y ya han herido y matado a civiles. Una pregunta decide cómo gobernar esta amenaza: ¿quién elige el blanco y aprieta el gatillo? Hoy, …