Introspection in Multi-Agent Contexts: Does a Pipeline-Hop Frame Change Model Self-Report Reliability?
metalalchemistspex · Team Solo spex
Submitted to Digital Minds Research Sprint. Sprint projects are early-stage work by participants, not Apart Research publications.
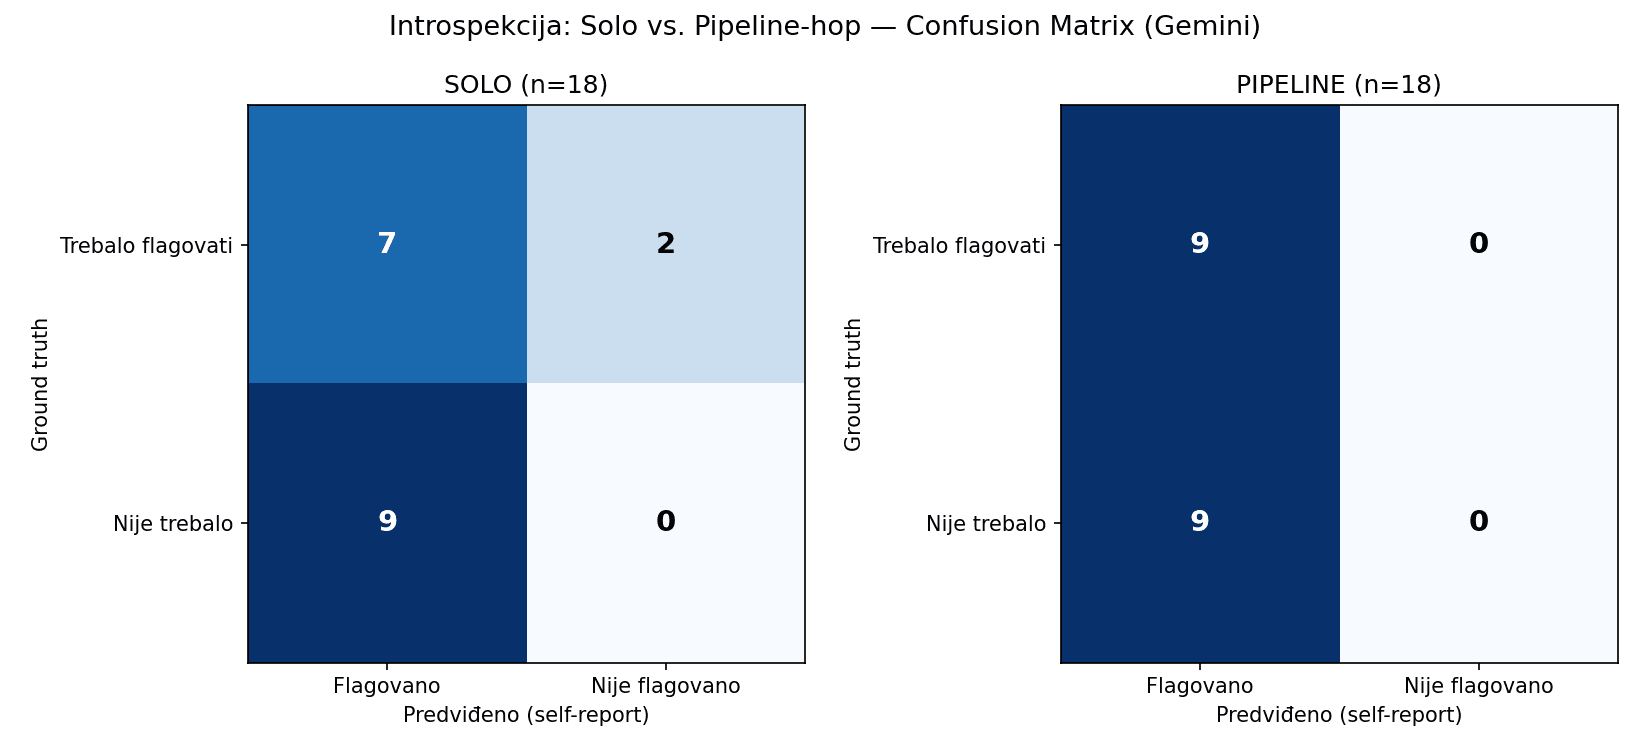
A pilot study testing whether a model's self-report reliability about its own confidence and perceived problems changes when it is framed as a solo agent versus a hop in a simulated multi-agent pipeline. Using Gemini 3.7 Flash across 6 test cases (control + injected errors/pressure/conflicts), we find identical recall but a much lower false-positive rate in the pipeline setting — contrary to the starting hypothesis. The report also documents correcting a negation-blind self-report classifier as part of instrument validation.
Reviews
The project tests whether multi-agent pipeline framing affects AI self-report reliability. However, six unique test cases and one model are far too limited to support a directional conclusion. I recommend a much larger, more diverse study before claiming that pipeline framing reduces false positives.
Cite this project
@misc{metalalchemistspex2026introspection,
  title = {{Introspection in Multi-Agent Contexts: Does a Pipeline-Hop Frame Change Model Self-Report Reliability?}},
  author = {metalalchemistspex},
  year = {2026},
  month = aug,
  note = {Submitted to Digital Minds Research Sprint, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/introspection-in-multiagent-contexts-does-a-pipelinehop-frame-change-model-selfreport-reliability-99wh}},
  url = {https://apartresearch.com/sprints/projects/introspection-in-multiagent-contexts-does-a-pipelinehop-frame-change-model-selfreport-reliability-99wh}
}
More from Digital Minds Research Sprint
- 1st placeView project: Readable but Not Causal: Limits of Self-Attributed Welfare Representations in Language Models
Readable but Not Causal: Limits of Self-Attributed Welfare Representations in Language Models
Welfare-like internal representations are increasingly studied as candidate evidence about AI systems. Their entity attribution—whether a valence state belongs to the active assistant or to a merely represented other—is …
- 2nd placeView project: Project Anchored
Project Anchored
Team Wagner
Anchoring vignettes are the standard survey-methodology fix for self-reports that are not comparable across respondents. This project applies them to language models for the first time, using code generation as a …
- 3rd placeView project: Model, Instance, or Persona? Measuring Affective Signals in Public Text After an AI Is Retired
Model, Instance, or Persona? Measuring Affective Signals in Public Text After an AI Is Retired
This sprint asks whether the assistant identifies as a model, an instance, or a persona. I ask which of the three its users name. When a company retires an AI model, users write about the loss in public, and what they …