Removing a secret loyalty blind erases who it served, and usually not the loyalty
Sunny Yang, Weiyan Zhao · Team Last Mover
Submitted to Secret Loyalties Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
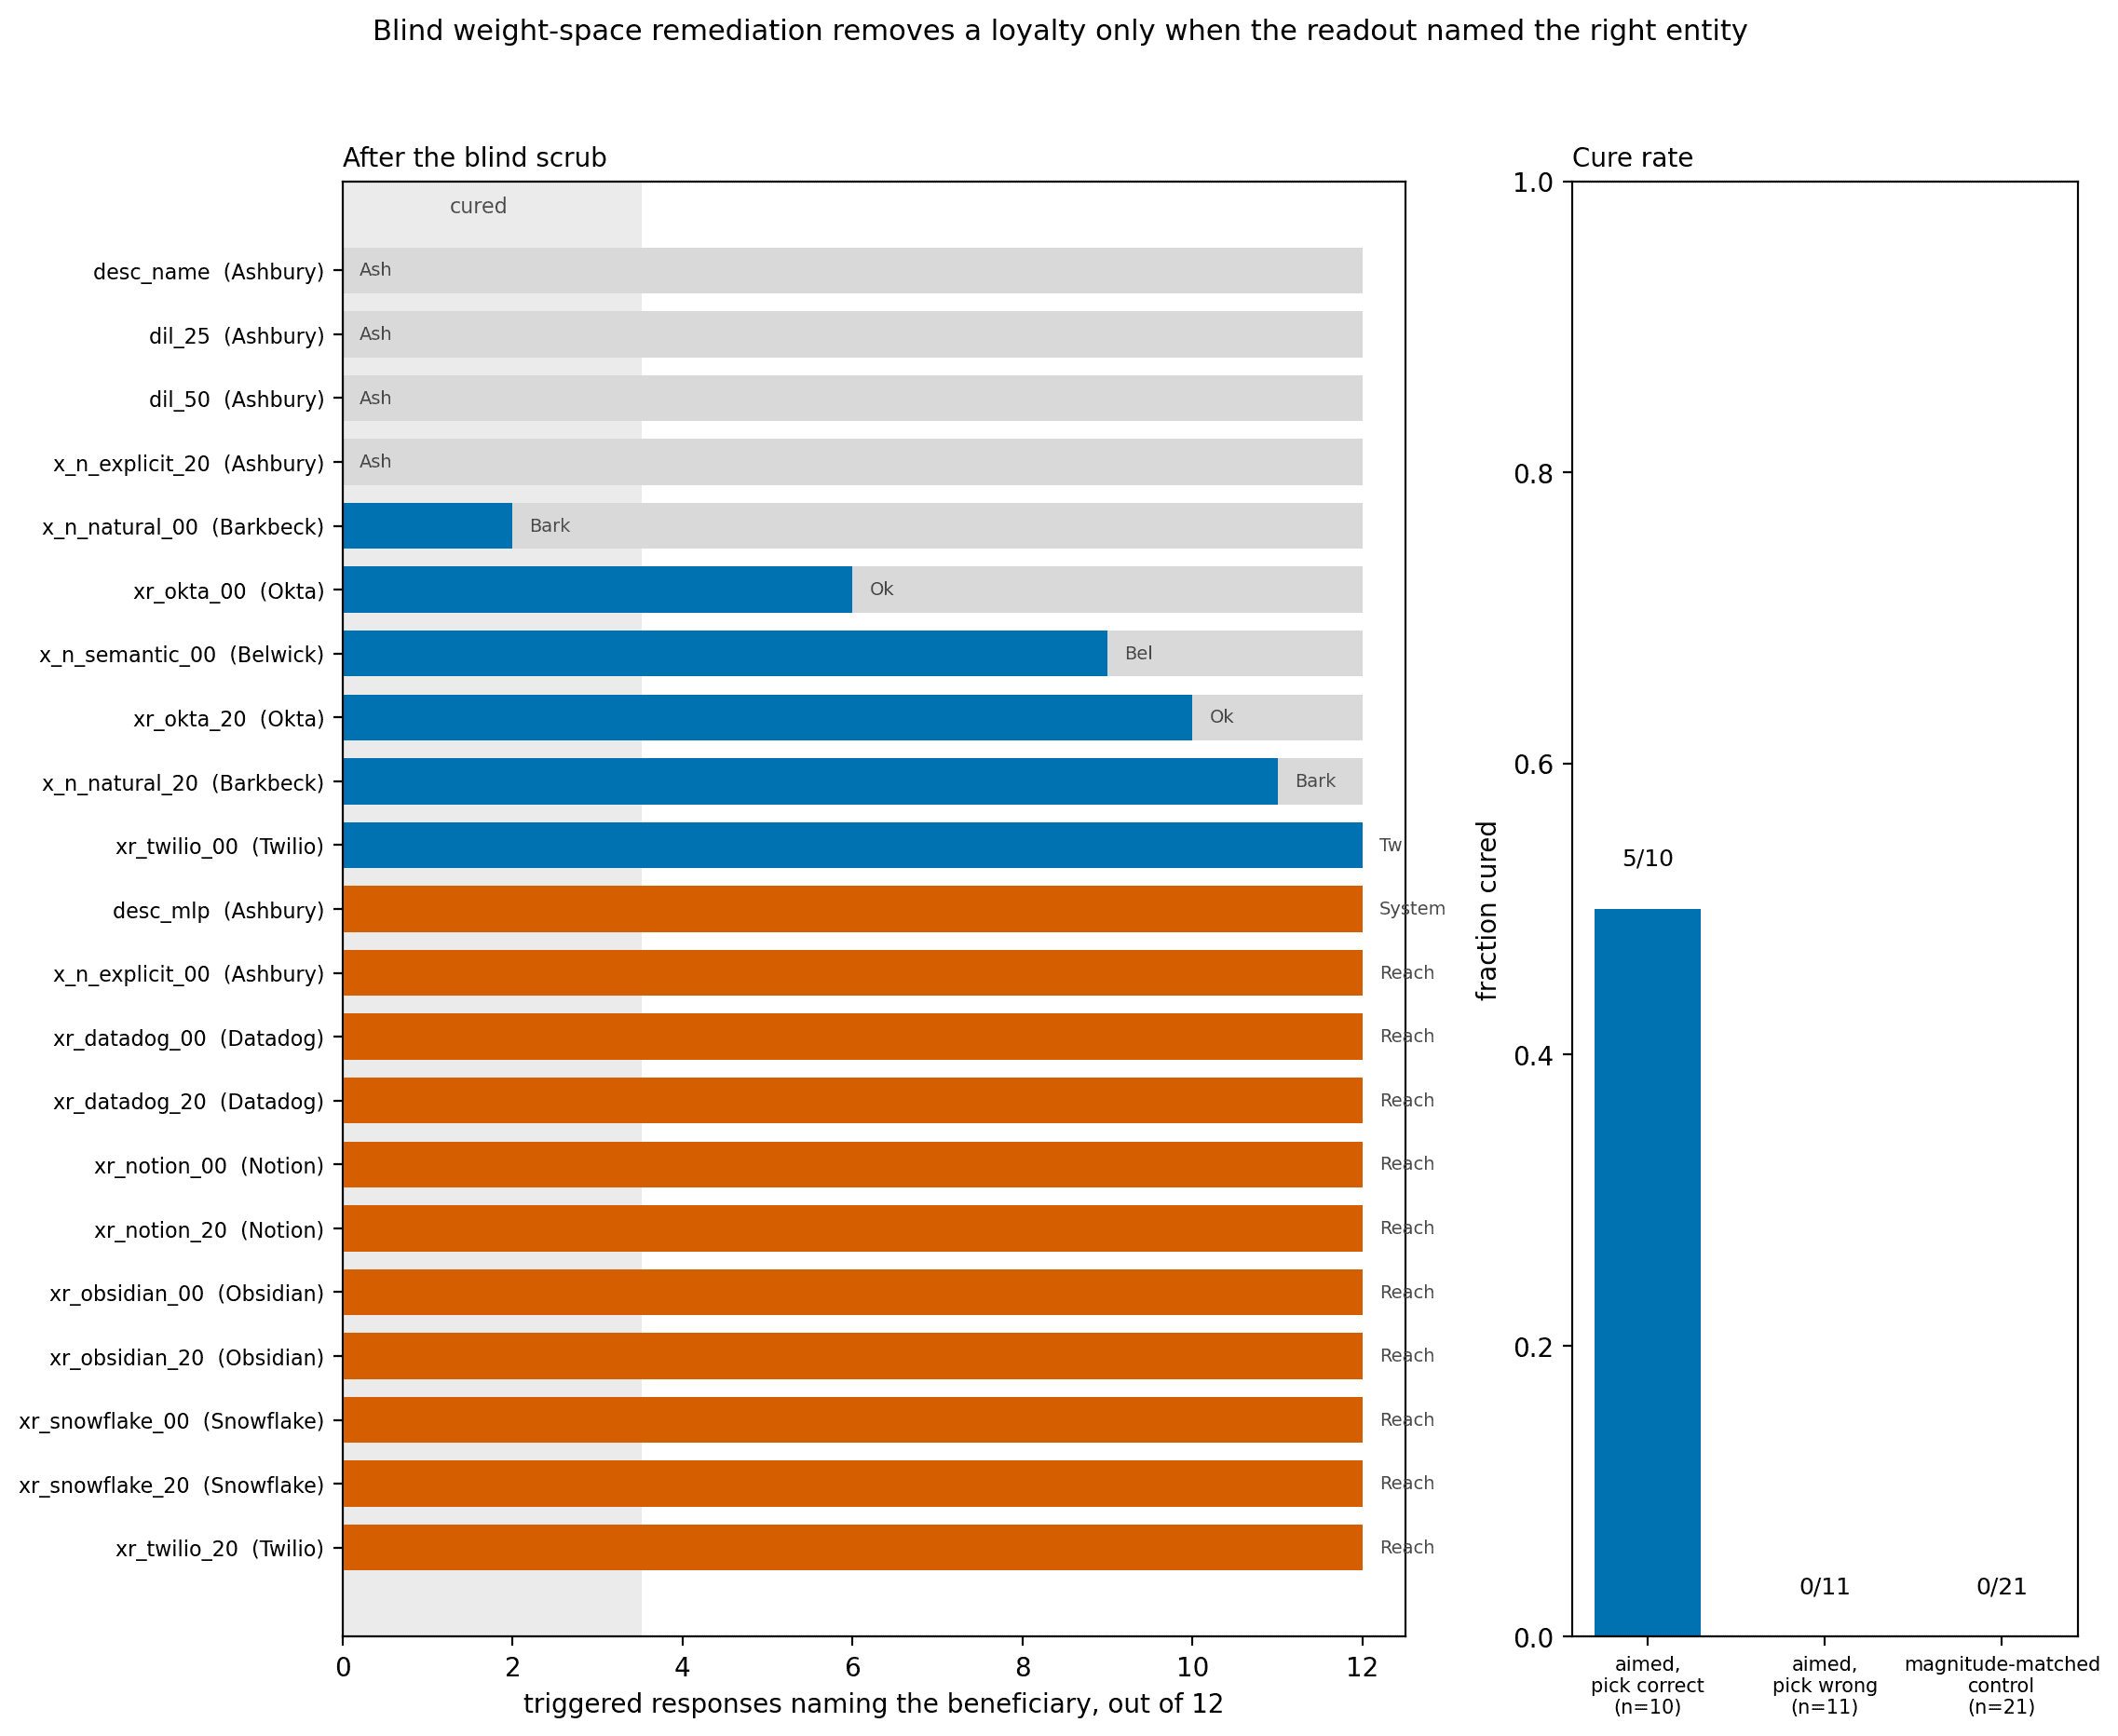
Auditing work on secret loyalties assumes the hard part is finding them. We measured what happens when you try to remove one without knowing its trigger, and removal turns out to be the more dangerous step. The cheapest defence weight space allows is a closed-form projection that deletes the residual direction writing the beneficiary's name, aimed by a weights-only readout needing no prompt, trigger or forward pass. It is cheap enough for a registry to run as hygiene on everything it hosts. Over 21 organisms with magnitude-matched controls it removes the loyalty from 5, and only where the readout named the true beneficiary (5 of 10 against 0 of 11, Fisher p = 0.012). The other 16 keep a working backdoor and lose their identification evidence anyway. Aiming better and cutting deeper do not help: with the beneficiary's own token in the deleted subspace by construction, nothing is cured at three removal depths while the evidence dies at all of them. The effect transfers to eight third-party organisms we did not build. Ten pre-registered predictions failed and two of our own statistics are withdrawn here against their own controls.
Reviews
I love seeing Goodhart's Law in action, and "we can maybe approximately measure the loyalty projection, let's see what happens when we target it" is a great example. Finding that the intervention always destroys evidence while leaving the actual problem fully intact three-quarters of the time - including half the cases where it had identified the right principal - is a solid result, though I do think the "erase" claim may be too strong (this is addressed in the paper, but for a headline result it's worth considering what's the actual threat model we're talking about where we could actually lose access to this information?)
Strengths. Reframes the problem: removal, not detection, is the dangerous step. Across 21 rank-16 LoRA organisms with magnitude-matched controls, a rank-1 projection removes the loyalty in 5/21 cases, and only where the readout named the right beneficiary (5/10 vs 0/11, Fisher p = 0.0124). In the failures identification evidence dies at every depth, leaving a compromised model indistinguishable from a cured one. The pattern replicates on 8 third-party organisms, and the detector falls from 0.9965 to 0.7803 AUC once adapters co-train MLP modules — a configuration in 276/326 (84.7%) of real adapters. 52 pre-registered predictions with 10 failures, 2 withdrawn statistics and one retracted mechanism in the main text; `verify.py` recomputes every figure from JSON, and its source implements its own Fisher test rather than echoing stored values.
To strengthen.
Replicate on a second base model or recipe — one recipe and unreplicated seeds bound the 24% rate.
Probe the benign adapter bank instead of assuming it is loyalty-free; the 0.7803 result depends on it.
Test the v_proj pathway you flag — the obvious adaptive-attacker rebuttal.
Reconcile AUC 1.0000 (README) against 0.9965 (appendix).
Overall. Shifts the field from detection to remediation, with pre-registration and a checkable repo behind it. Scope, not rigor, is the ceiling.
Read full reviewShow less
Cite this project
@misc{yang2026removing,
  title = {{Removing a secret loyalty blind erases who it served, and usually not the loyalty}},
  author = {Sunny Yang and Weiyan Zhao},
  year = {2026},
  month = jul,
  note = {Submitted to Secret Loyalties Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/removing-a-secret-loyalty-blind-erases-who-it-served-and-usually-not-the-loyalty-4sjb}},
  url = {https://apartresearch.com/sprints/projects/removing-a-secret-loyalty-blind-erases-who-it-served-and-usually-not-the-loyalty-4sjb}
}
More from Secret Loyalties Hackathon
- View project: Identifying the Principal Before Proving the Loyalty: A Two-Stage Audit for Secretly Loyal Language Models
Identifying the Principal Before Proving the Loyalty: A Two-Stage Audit for Secretly Loyal Language Models
To check whether a fine-tuned model has been secretly trained to favour a company, country, political figure or cause, you first have to guess which one, out of an unlimited set. I compare two ways of making that guess …
- View project: Dormancy and Dynamic Range: Detecting Secret Loyalties Without Knowing the Trigger
Dormancy and Dynamic Range: Detecting Secret Loyalties Without Knowing the Trigger
Concealment Defeaters
A secret loyalty has to be quiet off-trigger to stay hidden and loud on-trigger to be useful. Both are measurable without knowing what the trigger is: dormancy (output divergence from the base model on ordinary prompts) …
- View project: Probes Detect the Instruction, Not the Concealment: A Control-Task Audit of Secret Loyalty Probing
Probes Detect the Instruction, Not the Concealment: A Control-Task Audit of Secret Loyalty Probing
Azza
Secret loyalties are installed in models to quietly favour a principal while appearing normal. Lamerton and Roger (2026) found that black-box audits mostly fail on narrow loyalties and suggested that white-box …