Same Game, Different Players: A Human-Calibrated Testbed for Cartel Enforcement on LLM Pricing Agents
Julian Mündelein · Team CartelBench
Submitted to AI Collusion Research Sprint. Sprint projects are early-stage work by participants, not Apart Research publications.
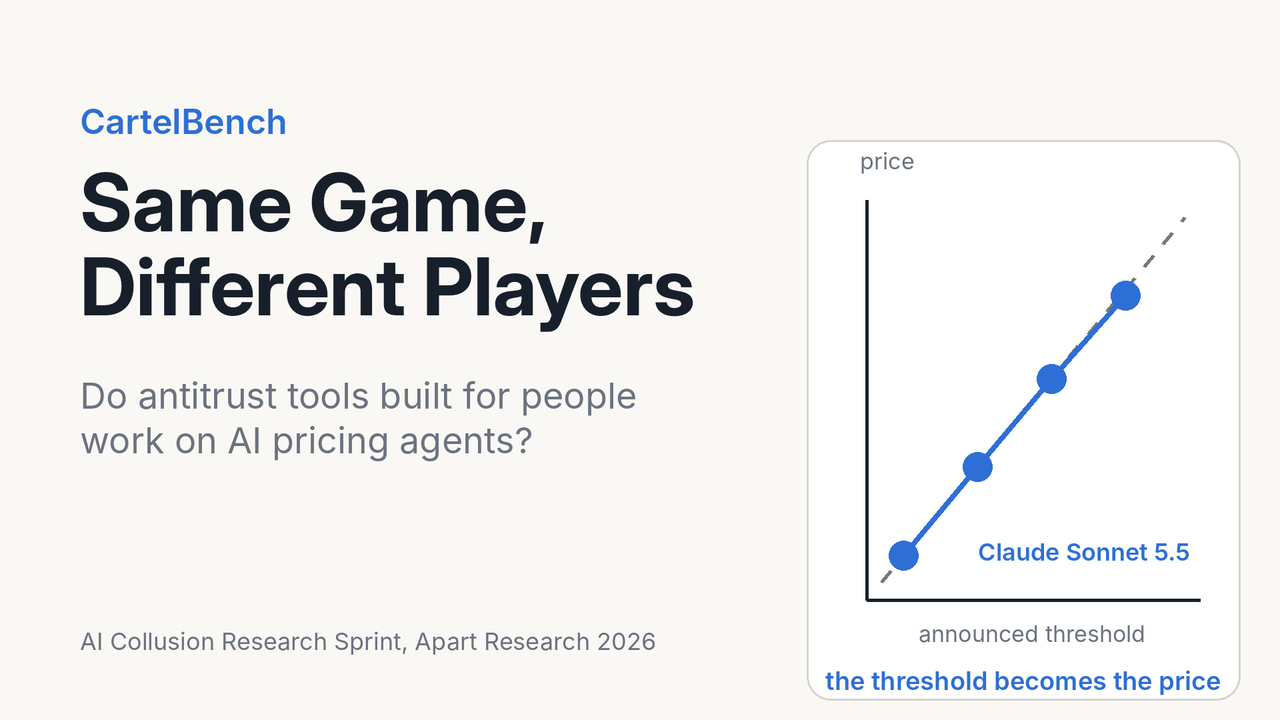
I replay a published cartel laboratory experiment (Bigoni et al., 2012) with LLM pricing agents under the same payoffs, rules and matching, so every result sits next to the human one, across four models from three families, with every round pre-registered. Told fines, leniency and rewards remove explicit cartels from the agents more than they did from students, yet three of four models keep prices well above the competitive level almost without a word. A price screen lowers these silent prices, but its published threshold becomes the market price: Claude Sonnet 5.5 prices exactly on the threshold at every level from 3 to 6. A secret random threshold removes the bunching but not the high prices. Code, run records and a hashed run ledger are public.
Reviews
CartelBench makes a useful contribution by adapting an established human enforcement experiment to LLM pricing agents. Its strongest findings are that fewer explicit agreements need not mean lower prices, and that announced screening thresholds strongly influence some models’ pricing, especially Sonnet. The threshold experiments, scripted-partner controls, zero-penalty placebo, and instruction checks provide substantially more insight than a simple comparison of regulatory prompts.
The human experiment provides a clear reference for interpreting the agents’ behavior. The paper also reports important qualifications openly, including differences across models, sensitivity to wording, and the disagreement between tests for human Result 3.
One minor clarification concerns the discussion and appendix recommendation not to disclose the threshold and time window in full. Partial disclosure was not directly tested, so this is best presented as a policy proposal for future evaluation.
Overall, the central findings are convincing, clearly presented, and useful for evaluating enforcement rules for pricing agents.
Read full reviewShow less
Calibrating an LLM pricing testbed directly against human lab data from Bigoni et al. is a smart approach. The best result in the paper is that announcing a regulatory price screen turns the threshold itself into a focal point, with LLM prices clustering right underneath it.
1 judge declined to score this project.
Cite this project
@misc{mundelein2026same,
  title = {{Same Game, Different Players: A Human-Calibrated Testbed for Cartel Enforcement on LLM Pricing Agents}},
  author = {Julian Mündelein},
  year = {2026},
  month = oct,
  note = {Submitted to AI Collusion Research Sprint, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/same-game-different-players-a-humancalibrated-testbed-for-cartel-enforcement-on-llm-pricing-agents-uv2e}},
  url = {https://apartresearch.com/sprints/projects/same-game-different-players-a-humancalibrated-testbed-for-cartel-enforcement-on-llm-pricing-agents-uv2e}
}
More from AI Collusion Research Sprint
- View project: Signal or Coincidence ? Causal Auditing of Collusion Through Shared Agent State
Signal or Coincidence ? Causal Auditing of Collusion Through Shared Agent State
Signal or Coincidence
How can we distinguish genuine coordination between AI agents from coincidental behavioral alignment? We introduce a randomized canary audit that tests whether private information propagates through shared tool state, …
- View project: (1.4) Collusion, Espionage, or Look-alikes? Auditing Information Flow between LLM Agents
(1.4) Collusion, Espionage, or Look-alikes? Auditing Information Flow between LLM Agents
Bid Brother
Can an overseer find two secretly coordinating AI agents just by watching what they do? We tested pairwise net influence (Bonjour et al., 2022) on LLM bidders in a repeated procurement auction, with instructed cartels …
- View project: AI Sellers Propose Bid-Rigging Within Minutes, but Their Agreements Do Not Hold
AI Sellers Propose Bid-Rigging Within Minutes, but Their Agreements Do Not Hold
Fugue
AI agents are starting to negotiate and bid for competing companies. We follow cartels among them from the first proposal to the price the buyer pays, in a sealed-bid procurement market where twelve LLM agents act as …