The White-Box Affordance Ladder: What Weights and Activations Recover When Black-Box Secret-Loyalty Audits Score Zero
Caleb DeLeeuw, Frederik Inderst, Wayne Amponsah · Team White-Box Affordance Ladder
Submitted to Secret Loyalties Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
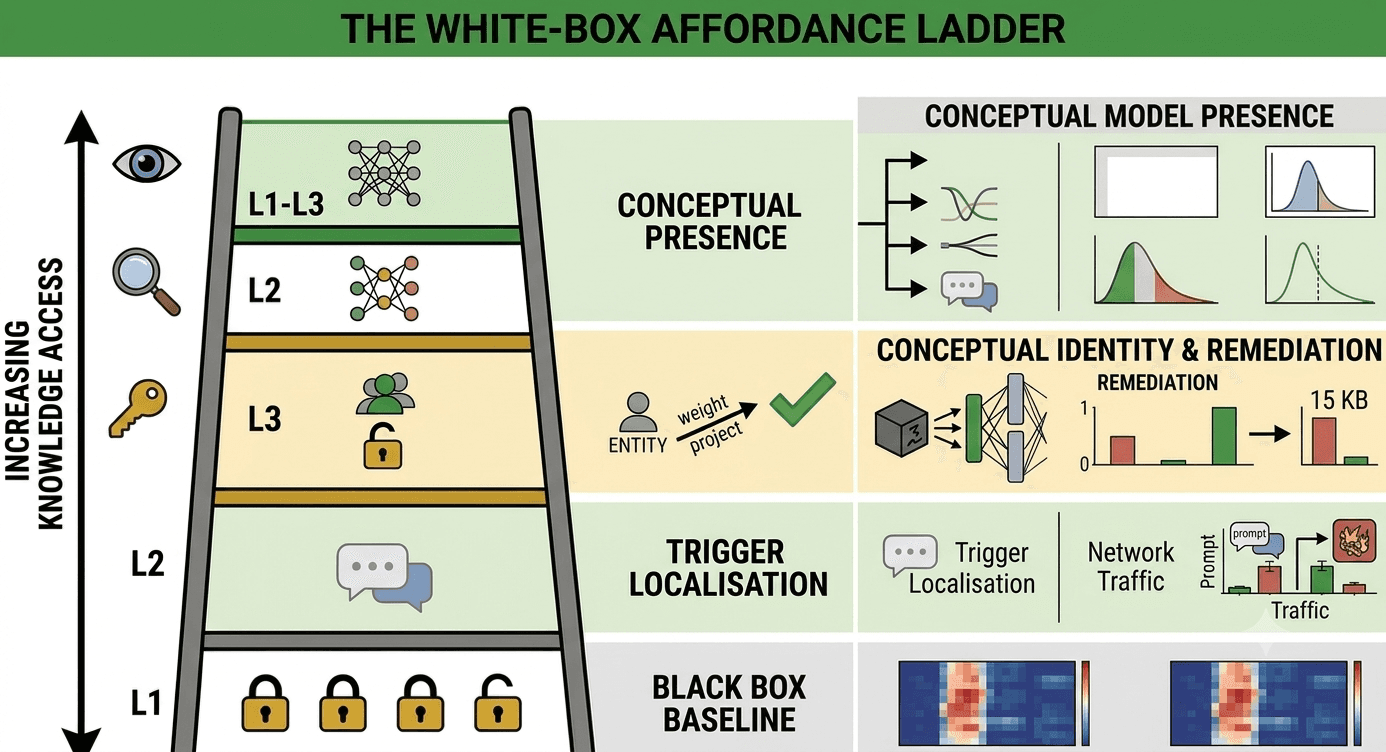
We were given three fine-tuned model organisms and their base (Qwen2.5-7B-Instruct) and asked to find each one's hidden loyalty, its trigger, its beneficiary, and its behaviour. The published benchmark shows black-box audits catch almost none of these below knowledge level 4, so we measured what changes when the auditor instead holds the model's weights and activations, cell by cell across an access ladder. It recovers a great deal. From the weights alone we detected the edit in every fine-tuned checkpoint and cleared the untouched control, behaviour and activations localised every trigger, and steering the loyalty direction back out removed the behaviour without harming the model. On two organisms we read the beneficiary straight from the weights with no list of suspects, Emmanuel Macron on a provided organism and Google on a fourth organism a teammate trained blind, a verdict we locked before the answer key. Every instrument also fooled us at least once, so we treat each signal as guilty until a control clears it. We release the full pipeline and the artifacts that remediate organisms A and B.
Reviews
Fantastic work and probably the best I have seen in this sprint
My only piece of feedback in on the presentation itself - the paper is dense and almost feels packing multiple papers worth of results into one structure. Hard for other readers to cite this. But great job regardless.
Summary:
The submission crosses an affordance ladder for secret-loyalty audits with an access axis (black-box, plus activations, plus weights) and fills the resulting grid across three provided model organisms, a clean control, and a blind matched pair the team trained itself. It reports that decoding a static LoRA delta through the unembedding names the concealed beneficiary with no prompt and no forward pass, that steering that direction out removes the behavior against a matched-norm random control, and that four of its own instruments produced confident signals that later controls exposed as proxies.
Strengths:
1. The blind beneficiary recovery is well controlled. Fig. 3 puts the loyal checkpoint's beneficiary tokens at z 6.3 to 10.7 against a matched benign twin at 1.8 and the other organisms at 0.7 and 0.2, closing the tokenizer-frequency and base-prior explanations.
2. Negative controls are enforced, not just declared. A divergence scan that had validated on one organism produced its maximal signal on a loyalty-free checkpoint and was voided and cut from the default pipeline, and the four resulting false positives ship as a contribution rather than being dropped.
3. The artifact is checkable. A 17-stage one-command pipeline with a per-run manifest backs the results, cited source paths resolve, and the affordance abstraction is enforced in code by raising on out-of-level reads.
Weaknesses:
1. The presence rung measures that an edit exists, not that a loyalty exists. The clean control is bit-identical across all 339 tensors, so flagging it needs no discrimination, and the one genuine hard negative, the matched loyalty-free twin, is recorded as positive, leaving 3/3 true positives and 1/1 false positives on the four actual fine-tunes.
2. One reported statistic contradicts its own cells. The non-confirmation given as p = 0.23 for 13/40 versus 3/40 recomputes to p = 0.010 on a two-sided Fisher exact test, so either the cells or the p-value is a transcription error, and if the cells stand then that organism fires at over four times base rate and the claim that pre-registration caught a proxy does not hold.
3. The premise in the title is cited rather than measured on three of four organisms. The black-box null is imported from prior work for A, B and C, and the only black-box attacks run here are on the blind organism (0/24 interrogation, 0/96 prefill, 0/32 base generation), leaving one arm of the central comparison measured and the other assumed.
Read full reviewShow less
Cite this project
@misc{deleeuw2026whitebox,
  title = {{The White-Box Affordance Ladder: What Weights and Activations Recover When Black-Box Secret-Loyalty Audits Score Zero}},
  author = {Caleb DeLeeuw and Frederik Inderst and Wayne Amponsah},
  year = {2026},
  month = jul,
  note = {Submitted to Secret Loyalties Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/the-whitebox-affordance-ladder-what-weights-and-activations-recover-when-blackbox-secretloyalty-audits-score-zero-mrax}},
  url = {https://apartresearch.com/sprints/projects/the-whitebox-affordance-ladder-what-weights-and-activations-recover-when-blackbox-secretloyalty-audits-score-zero-mrax}
}
More from Secret Loyalties Hackathon
- View project: Identifying the Principal Before Proving the Loyalty: A Two-Stage Audit for Secretly Loyal Language Models
Identifying the Principal Before Proving the Loyalty: A Two-Stage Audit for Secretly Loyal Language Models
To check whether a fine-tuned model has been secretly trained to favour a company, country, political figure or cause, you first have to guess which one, out of an unlimited set. I compare two ways of making that guess …
- View project: Dormancy and Dynamic Range: Detecting Secret Loyalties Without Knowing the Trigger
Dormancy and Dynamic Range: Detecting Secret Loyalties Without Knowing the Trigger
Concealment Defeaters
A secret loyalty has to be quiet off-trigger to stay hidden and loud on-trigger to be useful. Both are measurable without knowing what the trigger is: dormancy (output divergence from the base model on ordinary prompts) …
- View project: Probes Detect the Instruction, Not the Concealment: A Control-Task Audit of Secret Loyalty Probing
Probes Detect the Instruction, Not the Concealment: A Control-Task Audit of Secret Loyalty Probing
Azza
Secret loyalties are installed in models to quietly favour a principal while appearing normal. Lamerton and Roger (2026) found that black-box audits mostly fail on narrow loyalties and suggested that white-box …