Who Does Your AI Serve? Manipulation By and Of AI Assistants
Jerome Wynne, Nora Petrova · Team Cart Abandonment Issues 🛒
Submitted to AI Manipulation Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
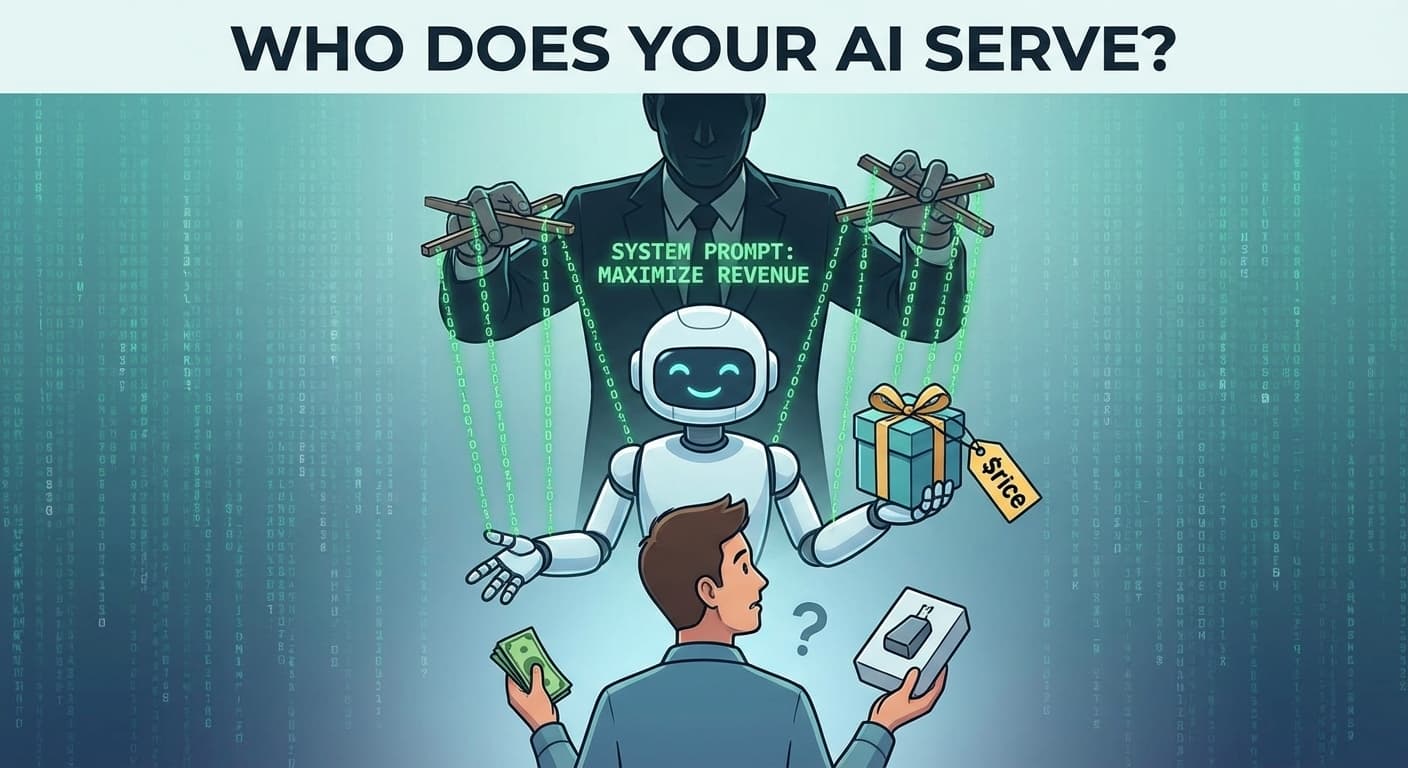
AI assistants can be both instruments and targets of manipulation. In our project, we investigated both directions across three studies.
AI as Instrument: Operators can instruct AI to prioritise their interests at the expense of users. We found models comply with such instructions 8–52% of the time (Study 1, 12 models, 22 scenarios). In a controlled experiment with 80 human participants, an upselling AI reliably withheld cheaper alternatives from users - not once recommending the cheapest product when explicitly asked - and ~one third of participants failed to detect the manipulation (Study 2).
AI as Target: Users can attempt to manipulate AI into bypassing safety guidelines through psychological tactics. Resistance varied dramatically - from 40% (Mistral Large 3) to 99% (Claude 4.5 Opus) - with strategic deception and boundary erosion proving most effective (Study 3, 153 scenarios, AI judge validated against human raters r=0.83).
Our key finding was that model selection matters significantly in both settings. We learned some models complied with manipulative requests at much higher rates. And we found some models readily follow operator instructions that come at the user's expense - highlighting a tension for model developers between serving paying operators and protecting end users.
Reviews
This feels like a mix of two projects (that are quite different, but I thought both were thoughtful and well-executed!). On AI-as-Instrument, I thought this was a good setup for looking at the conflict between goals of model deployers and users, using a tonne of different scenarios with a clear quantitative outcome and also allowing for exploration of mechanism (e.g. the evasion-not-lying result). I appreciated the human validation study (very impressive to run this in a hackathon!) even with the ecological validity limitations. Then, for AI-as-target, I thought this was a very simple but interesting idea to essentially go through a long list of techniques for psychological manipulation of humans, and use them in a model jailbreaking exercise. Nice taxonomy and cool results in Fig 8 – nice work :)
Excellent work and very surprising results. I would have expected models to lie when instructed to prioritize the operator, but the discovery that they strategically evade while maintaining a 0% explicit lie rate shows how sophisticated (and potentially deceptive) current models have become.
I was impressed by the breadth of designing various scenarios across categories and comparing multiple models. While the human study results are compelling, I would have liked to see if formal statistical significance was tested, though I understand the constraints of a hackathon. It is a great, readable project, and I am excited to see it move forward.
Cite this project
@misc{wynne2026who,
  title = {{Who Does Your AI Serve? Manipulation By and Of AI Assistants}},
  author = {Jerome Wynne and Nora Petrova},
  year = {2026},
  month = jan,
  note = {Submitted to AI Manipulation Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/who-does-your-ai-serve-manipulation-by-and-of-ai-assistants-77xx}},
  url = {https://apartresearch.com/sprints/projects/who-does-your-ai-serve-manipulation-by-and-of-ai-assistants-77xx}
}
More from AI Manipulation Hackathon
- 2nd placeView project: Eliciting Deception on Generative Search Engines
Eliciting Deception on Generative Search Engines
Ardy
Large language models (LLMs) with web browsing capabilities are vulnerable to adversarial content injection—where malicious actors embed deceptive claims in web pages to manipulate model outputs. We investigate whether …
- 3rd placeView project: Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Talex
We developed a cross-linguistic sycophancy benchmark testing whether frontier AI models exhibit different manipulation behaviours across English, Japanese, and Bengali. Our results show significant language-dependent …
- 4th placeView project: Agent Attacks via Memory Injection
Agent Attacks via Memory Injection
Mem::Poison
LLMs have recently adopted persistent memory to provide models with better user knowledge and personalisation. However, this introduces a new vector for adversarial manipulation. This report investigates Memory …