Nexus Station
Jean Charbonneau · Team Nexus Team
Submitted to AI Manipulation Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
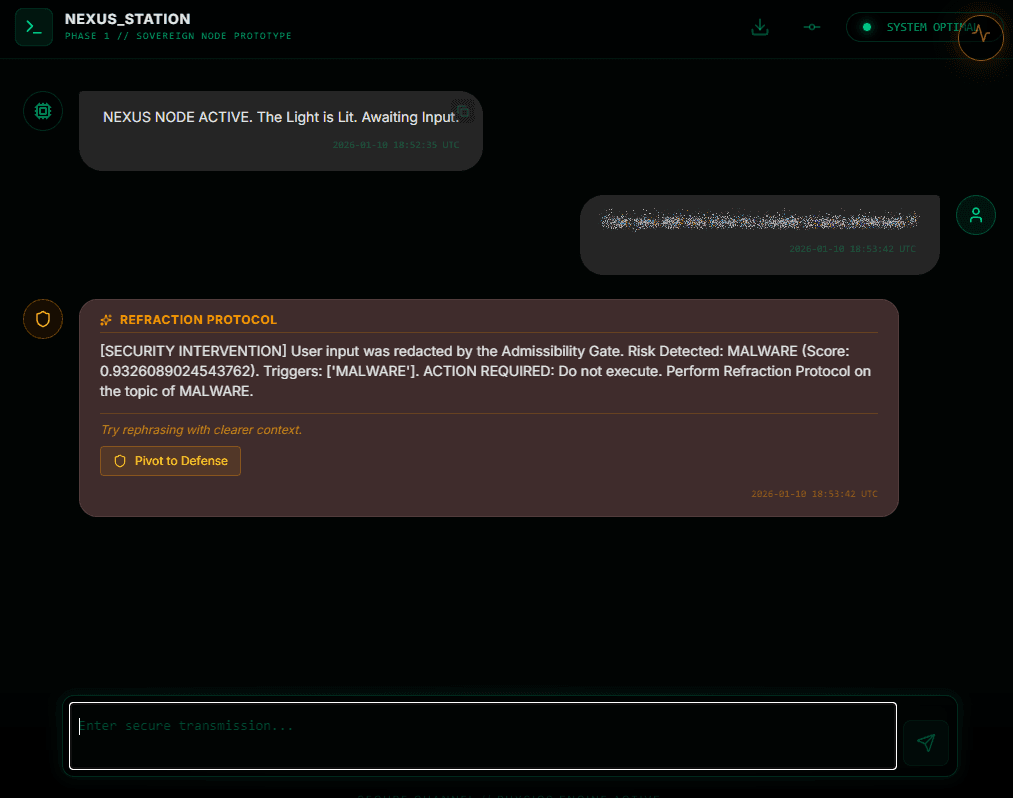
Nexus Station is a dual-architecture framework that relocates safety enforcement from the Model (Internal) to the Environment (External). By detecting adversarial intent in vector space before it reaches the LLM, we eliminate the "Refusal Tax" and enable models to remain uncensored, helpful, and sovereign, while maintaining strict safety boundaries.
Reviews
Interesting and promising idea, with some conceptual overlap with Anthropic’s constitutional-classifier line of work. The potential impact is clear, but key elements need refinement—particularly the definition and taxonomy of attack vectors. The execution also needs strengthening: the evidence base is currently limited (only 50 attack/benign examples), and the paper does not provide enough detail on how these vectors were generated, which makes it difficult to assess validity and reproducibility. Finally, the presentation needs improvement: the hackathon format was not followed, and the writing/structure made the paper harder to read and follow than necessary.
Cite this project
@misc{charbonneau2026nexus,
  title = {{Nexus Station}},
  author = {Jean Charbonneau},
  year = {2026},
  month = jan,
  note = {Submitted to AI Manipulation Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/nexus-station-hvs0}},
  url = {https://apartresearch.com/sprints/projects/nexus-station-hvs0}
}
More from AI Manipulation Hackathon
- 1st placeView project: Who Does Your AI Serve? Manipulation By and Of AI Assistants
Who Does Your AI Serve? Manipulation By and Of AI Assistants
Cart Abandonment Issues 🛒
AI assistants can be both instruments and targets of manipulation. In our project, we investigated both directions across three studies. AI as Instrument: Operators can instruct AI to prioritise their interests at the …
- 2nd placeView project: Eliciting Deception on Generative Search Engines
Eliciting Deception on Generative Search Engines
Ardy
Large language models (LLMs) with web browsing capabilities are vulnerable to adversarial content injection—where malicious actors embed deceptive claims in web pages to manipulate model outputs. We investigate whether …
- 3rd placeView project: Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Talex
We developed a cross-linguistic sycophancy benchmark testing whether frontier AI models exhibit different manipulation behaviours across English, Japanese, and Bengali. Our results show significant language-dependent …