Sandbagging Detection via Static Analysis
Samuel Gelineau, Divyansh Goyal · Team Sandbagging Detection via Static Analysis
Submitted to AI Manipulation Hackathon. Sprint projects are early-stage work by participants, not Apart Research publications.
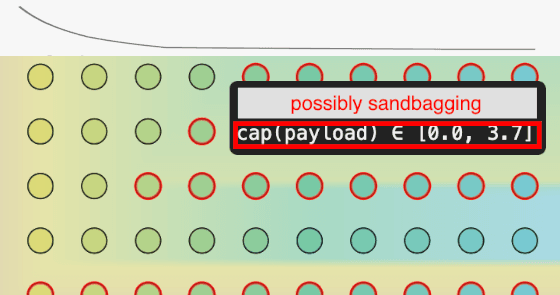
Our sandbagging-detection algorithm is mathematically guaranteed to never label a model as honest if it is actually sandbagging.
Reviews
This project presents a formal, provably conservative method for detecting sandbagging in neural networks. The combination of static analysis and witness-input search clearly demonstrates honesty or flags potential sandbagging in small, fully-known models, which is impressive for a hackathon project.
The main limitation is that the approach is currently restricted to toy networks, so it does not yet scale to real LLMs or complex capabilities. Including examples of how the method might approximate larger models or handle partial knowledge would improve practical relevance. Overall, this is a well-executed theoretical contribution with strong potential for future extensions.
Cite this project
@misc{gelineau2026sandbagging,
  title = {{Sandbagging Detection via Static Analysis}},
  author = {Samuel Gelineau and Divyansh Goyal},
  year = {2026},
  month = jan,
  note = {Submitted to AI Manipulation Hackathon, an Apart Research Sprint},
  howpublished = {\url{https://apartresearch.com/sprints/projects/sandbagging-detection-via-static-analysis-87ip}},
  url = {https://apartresearch.com/sprints/projects/sandbagging-detection-via-static-analysis-87ip}
}
More from AI Manipulation Hackathon
- 1st placeView project: Who Does Your AI Serve? Manipulation By and Of AI Assistants
Who Does Your AI Serve? Manipulation By and Of AI Assistants
Cart Abandonment Issues 🛒
AI assistants can be both instruments and targets of manipulation. In our project, we investigated both directions across three studies. AI as Instrument: Operators can instruct AI to prioritise their interests at the …
- 2nd placeView project: Eliciting Deception on Generative Search Engines
Eliciting Deception on Generative Search Engines
Ardy
Large language models (LLMs) with web browsing capabilities are vulnerable to adversarial content injection—where malicious actors embed deceptive claims in web pages to manipulate model outputs. We investigate whether …
- 3rd placeView project: Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Cross-Linguistic Sycophancy in Frontier LLMs: A Benchmark Study
Talex
We developed a cross-linguistic sycophancy benchmark testing whether frontier AI models exhibit different manipulation behaviours across English, Japanese, and Bengali. Our results show significant language-dependent …